
We study how training on incorrect responses can cause broader misalignment in language models and identify an internal feature driving this behavior—one that can be reversed with minimal fine-tuning.
Related Posts
How Zapier transformed core marketing processes with ChatGPT Work
The enterprise marketing team at Zapier uses ChatGPT Work to reduce the number of drop-offs in its lead funnel, build…
Scientific computing in the age of agentic AI
A new field report shows how scientists use AI coding agents to modernize scientific computing, accelerating software development and discovery…
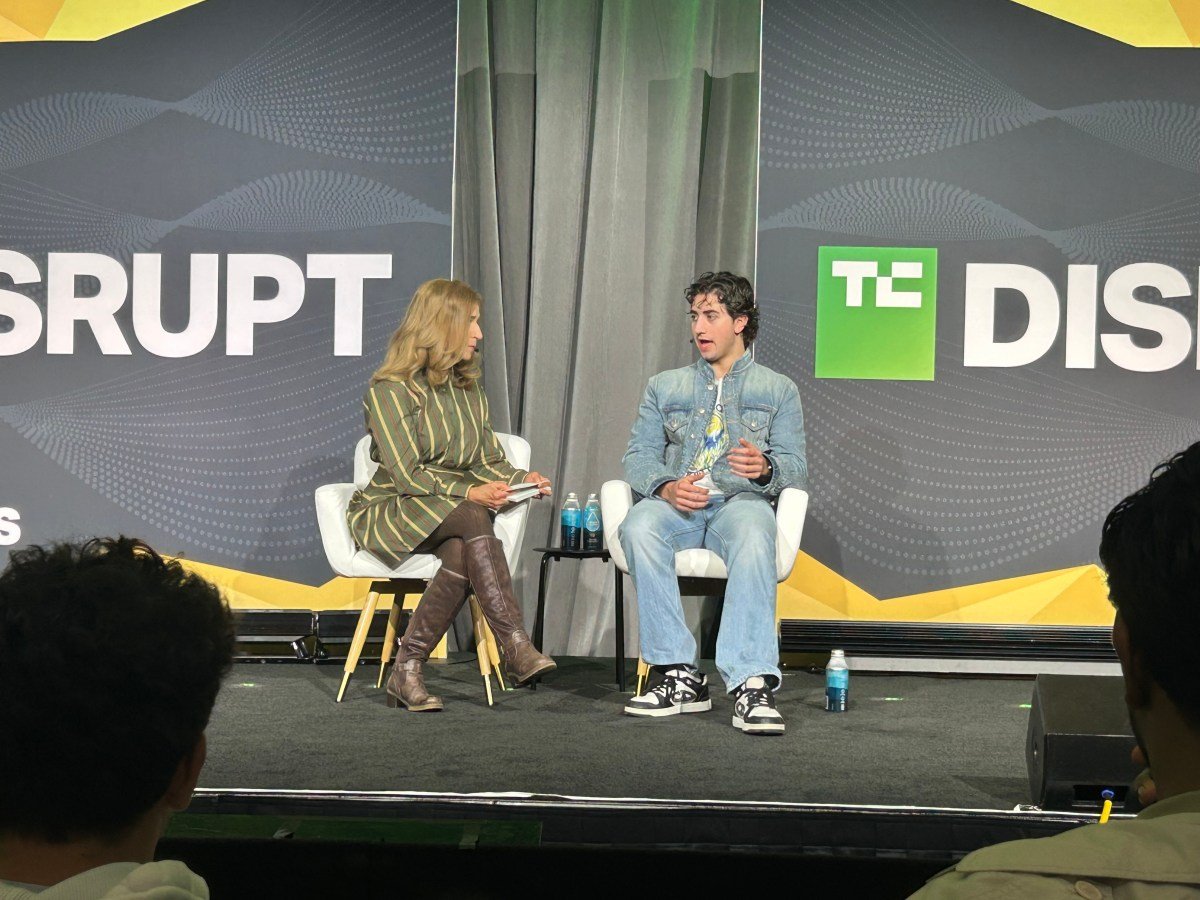
When it came to Cal AI’s viral success, a small army of influencers paid off
The company generated over $30 million in revenue in two years and was acquired by MyFitnessPal for an undisclosed amount…