We report on the recent publication of our retrosynthesis model RetroChimera in the journal Nature (opens in new tab).
The paper describes the model’s architecture as well as extensive validation studies, including the model’s ability to recall rare reaction types, and successful zero-shot transfer and fine-tuning on proprietary datasets.
We open-source RetroChimera’s implementation and weights in the hope that it will enable researchers to accelerate development of new medicinally relevant molecules and advanced materials.
Developing new medicines and materials requires making new molecules but planning how to make them is still largely manual, time-consuming, and costly. RetroChimera automatically proposes high-quality synthesis routes. The model combines two strong models with complementary strengths, learning how to rank their proposals to produce better predictions than either alone. In blind tests, PhD-level chemists prefer RetroChimera’s individual reaction predictions over preceding models and recorded literature reactions.
Custom-made molecules are unlocking advances in modern medicine, smart materials, and sustainable agriculture. Yet, progress is slowed by chemical synthesis—the time-consuming process of making new molecules from simpler building blocks in the lab. In addition, synthesis is a significant driver of drug development costs. So even as computational methods make it possible to explore large numbers of novel molecules, finding practical ways to synthesize them remains a critical challenge.
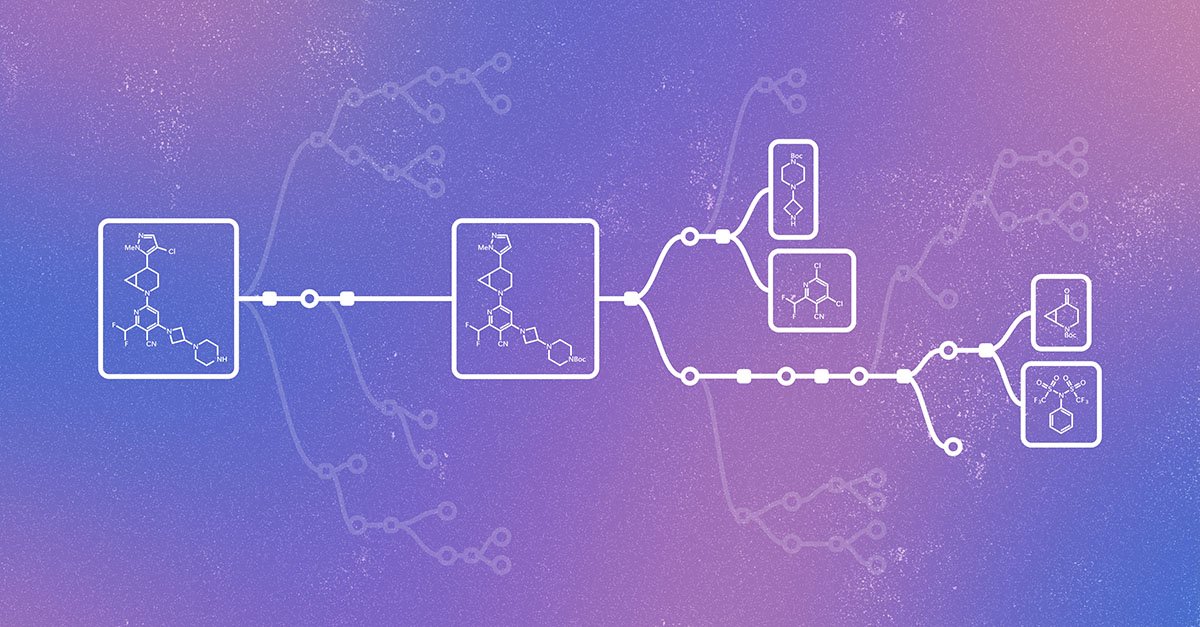
Figure 1: Planning a synthesis by working backward. Retrosynthesis starts with a target molecule and proposes successive disconnections into simpler precursors until purchasable building blocks are reached. The highlighted path shows a complete synthesis route; pale branches illustrate alternatives explored along the way. Circles represent molecules and squares represent reactions. For clarity, only a few branches are illustrated, with chemical structures shown for the target, one intermediate, and selected building blocks.
Retrosynthesis approaches this problem by working backwards from a target molecule, breaking it down step by step into simpler precursors (Figure 1). This process is comparable to playing strategic board games like chess and Go. It involves contemplating a wide range of possible immediate moves, or individual disconnections, while also requiring high-level strategic thinking to reach the end-to-end synthesis plan. However, the number of possible moves in retrosynthesis is much larger than in board games, and it is not obvious which moves would be available for a given molecule. Existing systems face major challenges, including recalling rare but strategically important reactions, robustness beyond the training distribution, and aligning with chemists’ expectations. As a result, retrosynthesis often requires highly specialized expertise, which hinders scaling and automation of scientific discovery.
Figure 2: Our framework for ensemble-based retrosynthesis with learned re-ranking which underpins RetroChimera. The ensemble receives a target molecule as the input, which is then processed by the sub-models. The model outputs are aggregated using a learning-to-rank strategy. While in this work we only investigate deep learning models as prediction sources (solid boxes), it is possible to add additional sources, for example calls to reaction databases or human-in-the-loop queries (dashed box).
In a paper recently published in the journal Nature (opens in new tab), we present RetroChimera (opens in new tab), a new framework for retrosynthesis prediction. It is built around two models (Figure 2). R-SMILES 2, a Transformer-based de-novo model, predicts precursor molecules directly from the input molecule. This gives it the flexibility to learn reaction patterns directly from data. However, its unconstrained generation can also make it prone to hallucination.
NeuralLoc, in contrast, is a graph neural network- (GNN) based model that encodes both the target molecule and reaction templates as graphs. It selects reaction templates and predicts where they should be applied to the target molecule. Its predictions are grounded in reaction patterns extracted from the training data, so it tends to produce more accurate and reliable outputs. But it’s more constrained when encountering reactions not covered by the template library.
These differences actually turn out to be a strength. Rather than making the same kinds of predictions, the two models capture complementary patterns in chemistry and specialize in different reaction types. R-SMILES 2 performs particularly well on reactions that involve large changes over the course of the reaction, while NeuralLoc excels in reactions of low precedence and those involving more localized changes.
RetroChimera combines the ranked predictions of both sub-models using a learned ensembling strategy. Each model assigns a learned, rank-dependent vote to each predicted reactant set, and votes are added when both models propose the same reaction. By learning how much to trust each model at different ranks, RetroChimera can leverage their complementary strengths, approximately matching the better-performing sub-model across reaction classes.
Figure 3: Expert assessment of multistep synthesis routes. Left: Ratings of individual reaction steps. Right: Complete routes accepted or rejected for ten challenging targets. RetroChimera succeeded on nine targets, versus five for the de novo model, four for the editing model, and two for NeuralSym, a strong baseline model.
As a result, RetroChimera performs strongly across both common and rare reaction classes and produces retrosynthesis predictions that better align with chemists’ judgment (Figure 3). In blind tests, expert chemists preferred disconnections of complex molecules suggested by RetroChimera over those obtained from its constituent sub-models, as well as those from more established approaches, and even from the test set itself.
We believe RetroChimera could help researchers identify promising synthesis route more efficiently, supporting faster design-make-test cycle across molecular science applications, including drug discovery and design of smart materials. RetroChimera could enable chemists to assess more—and more complex—candidate molecules at large scale. Paired with increasing levels of laboratory automation, we expect further acceleration toward closed-loop, self-improving systems for synthesis planning and execution.
We invite the broader chemistry community to experiment with RetroChimera, helping us identify its strengths and shortcomings so we can enhance it in the future. We are looking forward to hearing how it performs on various targets you care about!
Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking are our most advanced live dialogue models yet. Major upgrades in intelligence and parallel reasoning make them more intuitive to collaborate with and use to execute complex tasks using your voice.
Tom Ouyang
Principal Engineer
Malini Jaganathan
Member of Technical Staff, on behalf of the Gemini Audio Team
Listen to article
[[duration]] minutes
This content is generated by Google AI. Generative AI is experimental
Updated September 17, 2026
Today, we’re introducing two new models that bring advancements in near real-time reasoning to more effectively enable voice agents and make conversing with AI feel more intuitive and intelligent.
Gemini 3.8 Live: Built for scale and cost efficiency, combining conversational intelligence with fluid dialogue and visual grounding.
Gemini 3.8 Live Extended Thinking: Built for high-complexity tasks, with increased intelligence and multi-step reasoning.
For developers and enterprises, these models deliver the building blocks for reliable, production-ready voice agents. They also make speaking with Gemini across the Gemini app, Google Workspace, and Search more fluid and collaborative — helping you tackle complex tasks using just your voice.
Experience more fluid, intelligent conversations
Gemini 3.8 Live Extended Thinking provides enterprise-grade task completion and intelligence, capturing the #1 overall spot on Artificial Analysis’ Speech to Speech Quality Index (82.6), and leads in agentic task completion with 68.6% on τ-Voice and 35.1% on Sierra’s τ-Voice-banking benchmark. It also provides strong reasoning capabilities, scoring 97.7% on Big Bench Audio, while maintaining a highly competitive price point compared to other frontier models.
Gemini 3.8 Live has shown a high preference among users, securing a second place in the Speech Agent Arena. In addition to this performance, it remains highly cost-effective — providing developers and enterprises with a capable and efficient model built for scale.
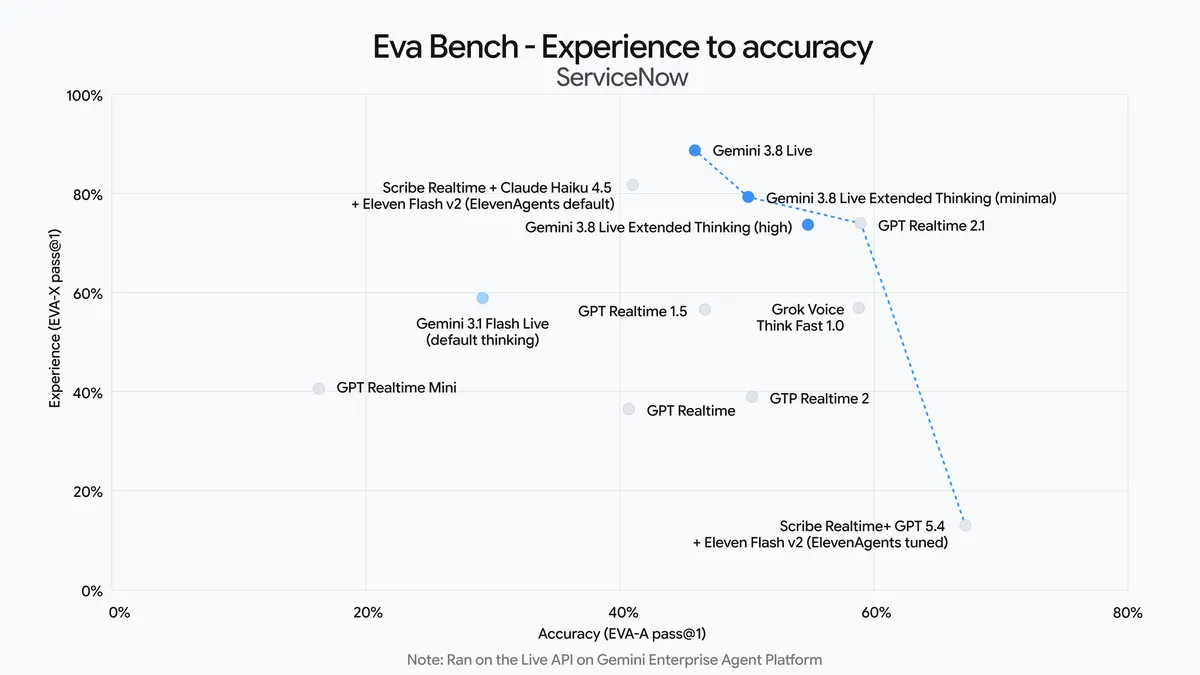
On ServiceNow’s EVA-Bench, a benchmark for evaluating voice agents, our models push the Pareto Frontier for complex workflows by successfully balancing accuracy with conversational quality.
Note: This was run on the Live API on Gemini Enterprise Agent Platform.
Gemini 3.8 Live processes visual inputs in near real-time, enriching conversations with context for more helpful responses. It automatically detects and transitions between 97 supported languages mid-conversation. It executes tools and API calls in the background while continuing the conversation, so the model can acknowledge requests and keep chatting while tasks finish in the background.
For tasks that require deeper reasoning, 3.8 Live Extended Thinking reasons and speaks simultaneously. It delivers increased intelligence for complex workflows while maintaining an uninterrupted conversational flow — using early verbal cues like “Let me check that…” to acknowledge prompts naturally, and live progress narration to walk users through multi-step background tasks as they progress.
Across Google Workspace, Search, and the Gemini app, our Live models deliver more intuitive, collaborative experiences — especially when tackling your most complex tasks.
Empowering the developer and enterprise voice ecosystem
By using the Gemini Live API, developer platforms such as Agora, Fishjam, LangChain, LiveKit, Pipecat, Vercel, and Vision Agents enable developers to build and deploy high-performance voice-driven interfaces with ease. These platforms manage complex real-time media streaming infrastructure behind the scenes, allowing developers to focus entirely on crafting the user experience.
We’re also partnering with companies like Salesforce, Genspark, and Lumeris who are excited about 3.8 Live and 3.8 Live Extended Thinking, highlighting its impressive latency, fluidity, and tool-calling capabilities.
Ensure transparency with SynthID watermarking
All audio generated by our AI products is watermarked with SynthID. This imperceptible watermark is woven directly into the audio output, ensuring AI-generated content remains detectable to help prevent misinformation. For details on our approach to safety and responsibility, review the model card.
How predicting the molecular impact of every possible single-letter DNA variant in the human genome will help accelerate our understanding of biology.
Today, we are introducing AlphaGenome Atlas: a platform (detailed in our paper) containing predictions for the effects of 9 billion single-nucleotide variants — every single-letter change possible — in the human genome. It is the most comprehensive catalogue of how genetic mutations affect molecular biology, and it is available for academic research through an intuitive and free-to-use website portal.
DNA is the language of life. Mastering it is a grand challenge that could transform our ability to understand biology and treat disease. But progress has been limited by a fundamental problem: interpreting how genetic variations impact biology at a molecular level. With roughly 9 billion possible single-letter mutations in the human genome, testing each one in the lab is practically impossible.
Google DeepMind has already made progress on this challenge with AlphaGenome, an artificial intelligence (AI) model that can predict how genetic variants impact biological processes. AlphaGenome is helpful for analyzing specific variants and has found widespread use in research, but we wanted to show researchers a big-picture view of variants across the entire genome.
By precomputing AlphaGenome’s predictions at scale, we have created an easily accessible resource that vastly expands the model’s reach. Just as an atlas is a collection of maps, linking together features of the land like altitude and location, AlphaGenome Atlas charts the molecular effects of DNA variants across the genome.
To help scientists quickly find the most impactful genetic changes, we are also releasing the AlphaGenome Variant Impact (AVI) score. The AVI combines the strengths of AlphaGenome and AlphaMissense — our model for predicting the impact of protein-altering DNA variants — condensing both models’ predictions into a single number. Now, researchers can rapidly rank variants and interpret their molecular effects at the same time.
Our trusted external collaborators have already used AlphaGenome Atlas to identify and experimentally verify key variants in unsolved rare disease research and find rare variants associated with common traits.
AlphaGenome Atlas is a massive 1-petabyte dataset, more than 30 times larger than the AlphaFold Database. When we expanded the AlphaFold Database in 2022, we grew the 3D structure information available from around 190K experimental structures to more than 200M structure predictions — covering nearly all catalogued proteins known to science. The database provided a portal that researchers with no coding experience could use, providing intuitive visualizations and making it easier to do large-scale protein structure analysis. It quickly became a crucial resource that drove discoveries across the life sciences and continues to accelerate researchers’ important work in countless fields.
In building AlphaGenome Atlas, we also aspire to make predictions more accessible and give scientists an intuitive way to explore a vast dataset.
AlphaGenome Atlas provides several powerful, interconnected resources, allowing researchers to link variants directly to the functional DNA sequences they disrupt.
Molecular effect predictions Atlas contains thousands of molecular effect predictions for each variant, across multiple important aspects of gene regulation, spanning hundreds of human and mouse cell types and tissues. This serves as the starting point for further resources.
AVI score A single number describing the impact for each genetic variant.
AVI feature attributions Each AVI score is also linked to distinct biological features driving it, such as the aspects of gene regulation predicted by AlphaGenome or the protein impact score from AlphaMissense.
DNA sequence motifs A comprehensive collection of over 2,500 recurrent DNA sequences — the “words” of the genome — and their locations.
Together, these resources support researchers for a wide range of genetic research tasks, from rapid variant ranking to deep dives into variant functions.
Extensive community collaboration guided the design of AlphaGenome Atlas. The AVI score helps researchers rapidly score and rank variants based on their potential impact. Crucially, it works for both coding regions (the 2% of the genome that codes for proteins) and non-coding regions (the remaining 98%), which orchestrates gene activity and houses most trait-associated variants.
Our testing shows that the AVI score provides best-in-class performance across many variant pathogenicity and rare disease benchmarks. To help interpret these scores, we also calculated AVI feature attributions that highlight which molecular processes — like RNA splicing or gene expression — are predicted to be most disrupted by each variant.
Overview of the AlphaGenome Atlas.(1) Precomputed effects are generated genome-wide for over 9 billion single-nucleotide variants. (2) From this, an allelic-resolution AlphaGenome Variant Impact (AVI) score is derived for each variant. To facilitate variant interpretation, AlphaGenome Atlas then decomposes the AVI score into additive feature contributions across interpretable categories such as chromatin accessibility, splicing, and conservation. (3) The precomputed variant effects, AVI score and the AVI feature attributions are linked, together with a compendium of genome-wide de novo motifs, which enables high-resolution mechanistic insights into variant function.
Real-world impact: From rare diseases to population genetics and molecular biology
AlphaGenome Atlas provides a high-resolution, global view of the genome. These large-scale predictions become most useful when applied to targeted research questions. By translating this data into actionable biological insights, our academic partners are already uncovering links between genetic variation and disease.
Understanding unsolved rare diseases. A major hurdle in understanding rare diseases is the daunting task of pinpointing the few causal variants hidden among thousands of candidates. In collaboration with the GREGoR Consortium, researchers applied the AVI score to prioritize these needle-in-a-haystack genetic variants for unsolved rare disease research. When Laura Covill and Anne O’Donnell-Luria from the Broad Institute and their colleagues used the AVI score to prioritize variants, driving a rare disease, that were overlooked in previous research, the team discovered a variant affecting a gene called DNM1, which is strongly linked to epileptic encephalopathy.
Crucially, the AlphaGenome predictions underlying the AVI score showed exactly how the variant functioned: it created an incorrect splice site (a mistake in the cell’s genetic instructions) that led to an abnormal extension of the resulting protein. Experimental screens validated the research prediction and found nearby variants with similar effects, showing that Atlas is a powerful tool for understanding impactful genomic variation.
Mapping rare variants associated with protein levels and complex traits. Moving beyond individual rare disease research, AlphaGenome Atlas can help uncover the genetic architecture of common traits in the general population. Identifying which rare, non-coding variants are associated with a specific trait or disease is notoriously difficult because the sheer volume of harmless genetic changes creates a statistical ‘background noise’.
To test how AlphaGenome Atlas can improve our ability to find non-coding variants affecting human traits, Gareth Hawkes, a Medical Research Council fellow at the University of Exeter, applied AlphaGenome Atlas to whole-genome data from over 54,000 UK Biobank participants, which made these elusive signals more obvious. By grouping rare variants based on their predicted molecular effects, Hawkes uncovered 22% more non-coding genetic associations, which would otherwise have not been detectable in the statistical noise. This let Hawkes pinpoint specific regulatory variants driving the abundance of critical proteins circulating in the human body, including PLA2G7 (linked to aging) and EGLN1 (a vital cellular oxygen sensor).
Taking this approach even further, Hawkes used AlphaGenome Atlas to look at how hundreds of millions of non-coding variants in the UK Biobank might be linked to body mass index. By focusing on the 1% of non-coding variants which Atlas predicts to be most impactful, he identified 19 genetic regions, which could help direct the next stage of targeted research into this trait.
Identifying the regulatory ‘words’ of the genome. Atlas can also be used to identify which recurring short sequences, or motifs, are driving different molecular processes in different cell types for different genes. These motifs can provide key clues, such as locating binding sites of transcription factors (proteins that turn genes on or off) and providing additional interpretation of non-coding variants. Julia Zeitlinger and Melanie Weilert at the Stowers Institute for Medical Research used this resource, for example, to categorize which transcription factors only affect the accessibility of DNA versus which ones are also able to turn genes on and off.
Accelerating genomic discovery
With AlphaGenome Atlas we are creating new layers of information that will help further our understanding of the human genetic code. We hope that this will be a valuable resource for scientists, but we also view it as a baseline rather than an endpoint. As our AI models like AlphaGenome improve, our maps of the entire human genome will become increasingly comprehensive and precise.
AlphaGenome Atlas is powerful in isolation, but it also represents a step towards our vision of a broad, unified solution for biologists. Its resources can be integrated into our broader agentic systems, like Google Antigravity, to help enhance end-to-end scientific workflows.
It is also important that AlphaGenome Atlas’ scientific knowledge is widely available, so we have made it accessible for non-commercial use through our website from today, as well as for commercial use on Google Cloud soon. (The AlphaGenome base model is already available for academic use on GitHub and via the AlphaGenome API, and also is available for commercial use on Cloud via Model Garden).
Together, these tools will enable researchers and industry partners to accelerate the pace of biological discovery: finding novel therapeutic targets, better understanding genetic disorders, and driving the next wave of targeted experimental validation.
Acknowledgements
We are grateful to our research collaborators at University of Exeter, Broad Institute, Boston Children’s Hospital, Stowers Institute for Medical Research, Harvard University, Memorial Sloan Kettering Cancer Center, Center for Genomic Medicine at Massachusetts General Hospital, and the University of Kansas Medical Center.
This work was done thanks to the contributions of Jun Cheng, Kyle R. Taylor, Lauren Nicolaisen, Joshua Pan, Clare Bycroft, Matteo Perino, Tom Ward, Raina W. Thomas, Natasha Latysheva, Gareth Hawkes, Laura E. Covill, Melanie Weilert, Maile J. Hirschmann, Xi Dawn Chen, Robin N Beaumont, V Kartik Chundru, Michael N Weedon, Simon Bourdareau, Hoyin Chu, Dhavi Hariharan, Thais Kagohara, Lucas Tenório, Yosuke Ushigome, Amanda Stafford, Courtney A. Shearer, Barbara Ikica, Ada Fang, Mouad Naciri, Victoria Johnston, Richard Green, Elisa Lai Hong Wong, Vincent Dutordoir, Anne Mottram, Adam Gayoso, Eirini Arvaniti, Guido Novati, Heidi L. Rehm, Fei Chen, Caleb A. Lareau, Caroline F Wright, Anne O’Donnell-Luria, Julia Zeitlinger, Pushmeet Kohli, Žiga Avsec.
We wish to thank our teammates and collaborators for their technical support, feedback, including Kathryn Tunyasuvunakool, Alexander Karollus, Risha Patel, Francesca Pietra, Alisha Eastep, Doga Fadillioglu, Charlie Taylor, Raphael Aboyeji, Uchechi Okereke, Gemma Gibbs, Olufemi Duduyemi, Juan Mateos-Garcia, Mariana Felix, Sahar Abdulrahman, Antonia Mould, Rachael Tremlett, Chang Yun, Salil Deshpande, Anshul Kundaje, Samantha Bryen, Greg Findlay, Phoebe Dace, Kinga Bujakowska, Emma Sherrill, Aubrie Soucy Verran, Boxun Zhao, Tim Yu, Francesca Pietra, Brendah Namugamba, Cassie Gray, Daniel MacArthur, Lingyi Wang, Marc Mansour, Mohamad Hajjari, Mounica Vallurupalli, Philip Montgomery, Phoebe Dace, Roisin Sullivan, Sam Bryen, Teresa Niccoli,
Finally we wish to thank Evie Gray, Adriana Fernandez Lara, Alex Wilkins, Danielle Breen, Mariana Montes, Inês Ayer, Ryan Smith, Ross West and Gaby Pearl for their expertise in communicating this work.
AlphaGenome
AlphaGenome: AI for better understanding the genome
Our flagship AI weather forecasting model now includes real-time satellite data, hourly refreshes, higher resolution, precise precipitation forecasting, and clean energy variables. It’s now integrated across Search, Gemini, Maps, Google Maps Platform, and Cloud.
Listen to article
[[duration]] minutes
This content is generated by Google AI. Generative AI is experimental
Every day, the weather influences billions of decisions. Some are as simple as grabbing an umbrella before heading out the door, but others are far more consequential. Wind, rain, and extreme weather events, like heatwaves and droughts, have cascading impacts across agriculture, global supply chains, clean energy production, and national economies.
In recent years, AI has revolutionized weather forecasting, using historical records to make faster and more accurate predictions than traditional methods. Yet predicting highly local and rapidly changing weather has remained a challenge. Previous models often lacked sufficient spatial resolution, and struggled to incorporate real-time weather data from sources like satellites.
Today, Google DeepMind and Google Research are introducing WeatherNext 3, the most advanced and accurate global weather model to date, according to independent live evaluations by Brightband. Our model learns directly from real-time observations, enabling it to provide timely and more localized predictions for the weather events that impact people the most. By using raw satellite data to produce a forecast every hour in high resolution, our model makes reliable forecasts accessible across Google products worldwide.
Rapid weather prediction at unprecedented resolution
A forecast’s utility often comes down to detail and how finely it resolves both time and space. WeatherNext 3 generates hourly forecasts at multiple spatial resolutions, maintaining physical consistency from broad global wind patterns all the way down to local topography.
With WeatherNext 3, we can visualize key surface variables — like temperature and moisture — at a 5-kilometer resolution, other surface variables at 10 kilometers, and atmospheric variables, like wind speed, at 25 kilometers. Overall, this provides a global weather picture roughly five times sharper than our previous model, WeatherNext 2, which produced forecasts on a 25-kilometer grid in 6-hour increments.
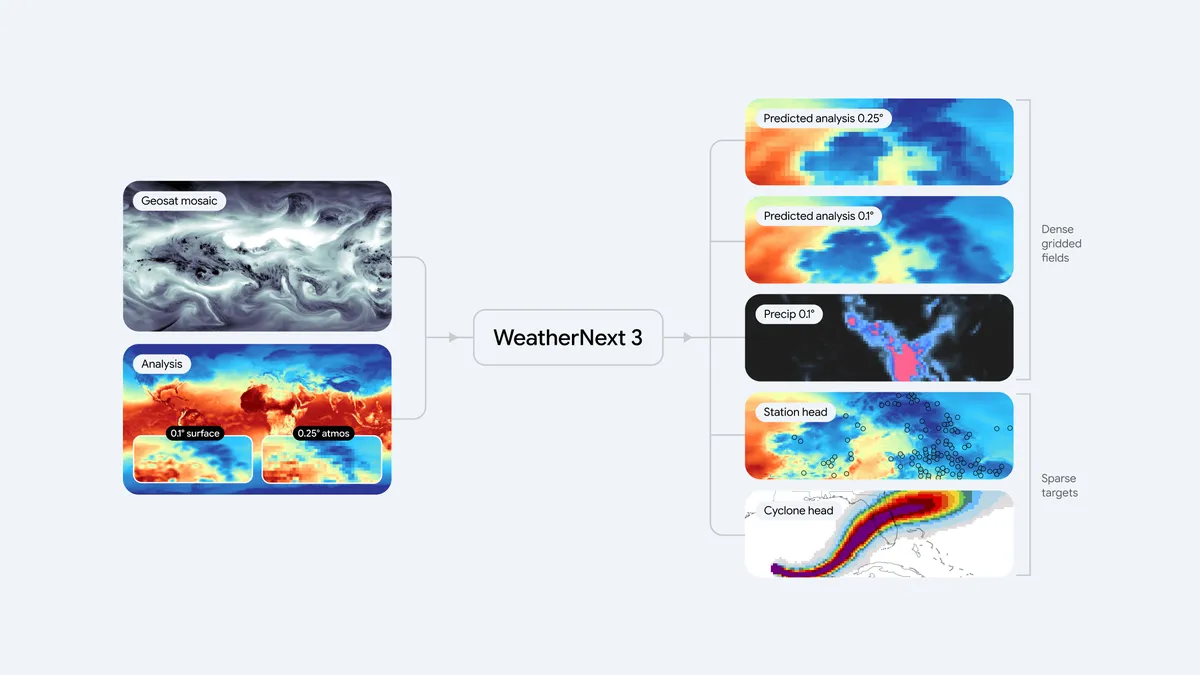
Figure 1: The end-to-end WeatherNext 3 system architecture. The model ingests live 1-hour geostationary satellite mosaics alongside traditional historical analysis to feed a single, flexible Functional Generative Network (FGN) mesh transformer. It outputs dense gridded fields, discrete cyclone tracks, and predicts station-level sparse coordinates natively.
Figure 2: Comparison of 2-meter temperature forecasts over the UK. WeatherNext 2 (left) at 25-kilometer (0.25°) resolution vs. WeatherNext 3 (right) at a native 5-kilometer (0.05°) resolution. WeatherNext 3 resolves the intricate local topography, preventing the pixelated, over-smoothed thermal representations seen in older models.
Real-world data at continuous global scale
WeatherNext 3’s biggest leap forward is what it learns from. Most AI weather models, including WeatherNext 2, are trained on data from numerical weather prediction (NWP) models. Although useful, NWP models are complex, supercomputer-driven physics simulations that carry a six-hour data lag. This lag can lead to biases for fast-changing variables like rain or surface temperature.
By ingesting a mosaic of live, global geostationary satellite data, our new model gains a rich, continuously updating view of the atmosphere. This allows the model to generate a new forecast every hour, each one grounded in the most recent satellite observations available, at up to 5-kilometer resolution.
This is important because critical weather develops fast. When storms, fronts, or precipitation systems materialize suddenly, our rapid update cycle and higher resolution provides earlier, more detailed insights needed to help drive an effective response.
Some variables, like temperature and humidity, can fluctuate dramatically over just a few kilometers, which is particularly relevant for communities near coastlines, valleys, or mountain ranges. Traditional models struggle here because they train on representations of the atmosphere that lack detail and miss extreme local variations.
To address this, WeatherNext 3 instead trains directly on sparse weather station observation data. This allows us to make global forecasts on a 5-kilometer grid that account for regional details like topography.
This breakthrough is particularly vital for regions across Latin America, Africa, and Asia-Pacific that have historically been underserved by high-resolution forecasting due to the immense supercomputing costs of traditional regional models. It brings localized, high-fidelity forecasting to billions of people and local businesses in these areas.
Beyond improved resolution and forecast frequency, our model introduces predictions specifically engineered for renewable energy production. The model forecasts 100-meter wind speeds (roughly at turbine-height) for precise wind-energy output, alongside high-resolution cloud cover and sun radiation levels to help solar farms estimate how much light they will receive on the ground.
This data is crucial for global clean energy planning, allowing grid operators and renewables developers to accurately predict how much power their clean energy assets will generate and match it with consumer demand.
Precipitation forecasting at breakthrough accuracy
Global weather models notoriously struggle to accurately predict precipitation. Rain and snow systems are driven by fast-moving cloud processes on tiny scales that are hard to model accurately using traditional physics-based simulations. Consequently, AI forecasts often produce blurry estimates or miss the boundaries of severe storms entirely.
To solve this, we train our model on two exceptionally high-quality sources of precipitation data: NASA’s satellite-based Integrated Multi-satellite Retrievals for GPM (IMERG) and our own global precipitation reanalysis based on satellite radar.
The result is a significant leap in precipitation forecasting accuracy. In medium-range global forecasts, evaluations against baselines show a Continuous Ranked Probability Score (CRPS) improvement of up to 60% against IMERG, 30% for MRMS, and 10% against rain gauge measurements for early lead times.
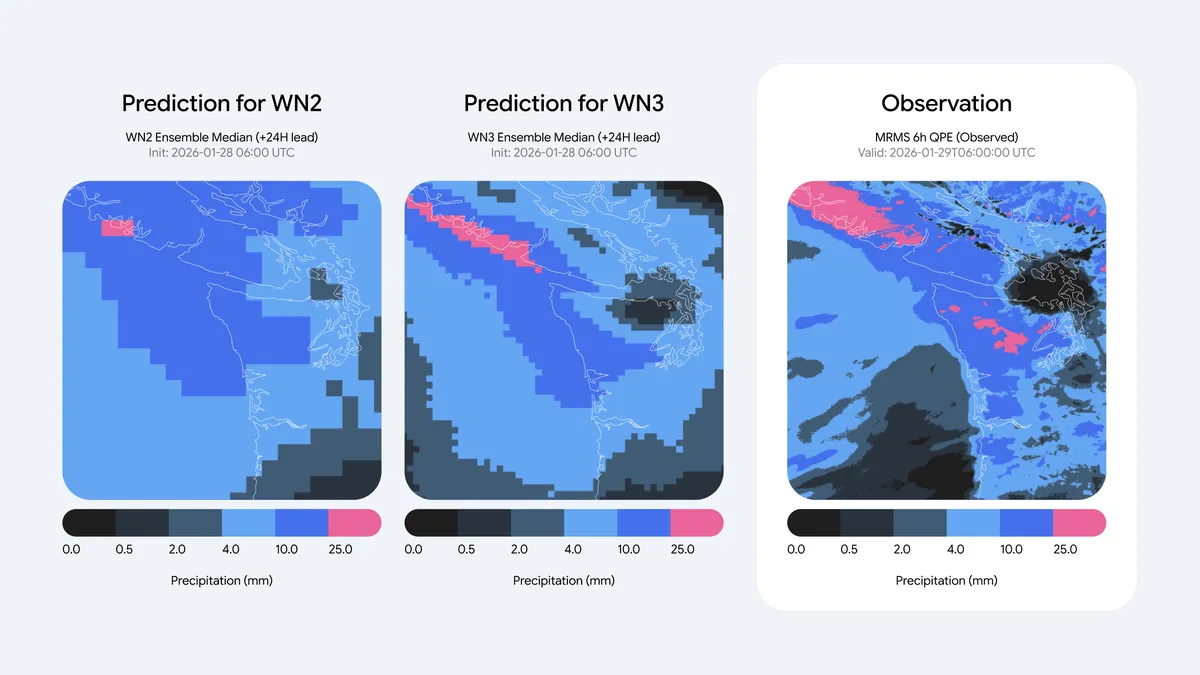
Figure 3: Medium-range probability of precipitation (PoP > 1mm) forecast comparison. WeatherNext 2 (left) at 25-kilometer resolution shows a highly diffused and pixelated precipitation footprint. WeatherNext 3 (middle) at 11-kilometer resolution closely mirrors the actual satellite ground truth (right), accurately capturing the sharp, convective bands of the weather systems.
Research applied across the ecosystem
Our primary goal is to advance weather intelligence to make it universally useful — whether for an emergency responder tracking sudden wind shifts, an air traffic controller planning flight paths, or a farmer managing crops.
To bring these breakthroughs out of the lab and into the real world, we’re integrating WeatherNext 3 across Google’s core ecosystem and beyond:
High-resolution forecast data: We’re making global weather predictions, updated hourly and ready to integrate into your workflows with no model setup required. This enables researchers, developers and businesses to query the data in BigQuery and Earth Engine, or bulk-download from Google Cloud Storage.
Available globally: WeatherNext 3 will begin powering weather experiences within Google Search, Gemini app, Google Maps, Google Maps Platform Weather API, and Google Earth Engine starting today. The update dramatically improves longer term forecasts. When planning a day or more ahead, people will see up to 50% more accurate precipitation forecasts — with the greatest improvements in regions where forecasts have historically been less reliable. So if you’re packing for a weekend trip or deciding the best day for an outdoor activity, you’ll now get more accurate predictions to help you plan.
The atmosphere will always retain a degree of unpredictability. However, by training on real-world observations and bypassing traditional modeling constraints, WeatherNext 3 brings us closer to a future where forecasts truly match what is happening on the ground.
Disclaimer: For official weather forecasts, severe weather warnings, and public safety advisories, please refer to your local meteorological agency or national weather service.
Today, we’re launching our Fairwind Program, a limited access program for governments and trusted partners to use our most advanced cyber defense capabilities.
Four Flynn
Vice President – Security and Privacy
Listen to article
[[duration]] minutes
This content is generated by Google AI. Generative AI is experimental
Defenders wanting to use advanced AI have faced a difficult dilemma: adopt enormous frontier models that could be expensive to deploy and difficult to control across enterprise codebases, or turn to smaller open-weight models that might struggle with complex vulnerability remediation and require teams to build their own tooling and infrastructure from scratch. Until now.
Today, we’re launching our Fairwind Program to bring the best of Google’s AI and cyber defense capabilities to a trusted group of Google Cloud customers, government agencies, and cybersecurity partners, to help them proactively solve cyber risks at scale. As a first step, the Fairwind Program will give defenders access to powerful and advanced Gemini models to help them autonomously find and fix vulnerabilities, protecting critical infrastructure, public services, and national security.
Finding and autonomously fixing vulnerabilities
The Fairwind Program offerings bring together our most advanced cyber model, Gemini 3.8 Flash Cyber, with our CodeMender harness, to help defenders find, verify, and fix vulnerabilities at agentic scale. Spotting weaknesses creates awareness and fear; autonomously finding and fixing vulnerabilities delivers security.
CodeMender with Gemini 3.8 Flash Cyber delivers the specialized reasoning to write and validate code fixes, at a fraction of the operating cost of traditional frontier models. Instead of taking weeks to manually fix vulnerabilities, defenders can now generate verified, deployment-ready patches in minutes — within an organization’s secure cloud environment.
Scaling frontline defense
Providing early access to these powerful cyber capabilities gives trusted defenders a vital adaptation window to harden their systems before bad actors have a chance to exploit new capabilities. We’re staging initial access to government and enterprise partners most critical to society’s resilience:
Governments and national cyber authorities: Hardening public-sector networks and citizen services against targeted intrusions.
Critical infrastructure operators: Protecting essential services across healthcare, telecommunications, energy, and financial networks from operational disruption.
Core technology platforms: Securing widespread software foundations to uplift digital security for millions of downstream users at once.
To ensure these powerful AI capabilities are used responsibly, participating organizations agree to strict operational standards, including limiting access to employees within their internal cybersecurity, incident response, or penetration testing teams and deploying protections like multi-factor authentication.
We have more than 650 participating partners globally, including:
What our Fairwind Program partners are saying
Trusted defenders and industry leaders are already putting Gemini 3.8 Flash Cyber into practice:
The Fairwind Program will evolve alongside our partners and users’ needs. We will adapt our product offerings and expand partner access, collaborating closely with industry, governments, and open-weight community leaders to strike the right balance between open access and robust security.
While we are prioritizing Gemini 3.8 Flash Cyber access for customers in the Fairwind Program, any Google Cloud customer can proactively secure their code by using CodeMender with publicly available models hosted on Gemini Enterprise Agent Platform, in combination with industry-leading solutions offered through AI Threat Defense.
Making an ecosystem-scale impact on cyber defense
Years of Google’s pioneering zero-trust architecture, advanced AI defenses, and built-in security allow us to protect billions of accounts daily – keeping more people and organizations safe online than anyone else. The Fairwind Program builds on this experience and is part of our broader commitment to global cyber resilience across the entire digital ecosystem, including helping to fortify grassroots cyber defense.
Through Google.org, our latest commitment brings our total cybersecurity funding to more than $100 million globally. We’re pleased to release our 2026 Google.org US Cybersecurity Impact Report, which details $36 million in funding for 35 cyber clinics to date, providing free, hands-on security support to over 1,250 hospitals, public school districts, and municipal utilities in the U.S.
Providing a security advantage
The defender’s edge comes from shrinking the time between detecting a flaw and patching it. Through Google’s Fairwind Program, government and enterprise partners gain autonomous tools to repair systems faster and at scale, keeping them one step ahead of agentic-speed threats.
The Flash family extends GigaPath and GigaTIME with dramatically improved efficiency, making large-scale pathology research more accessible and practical.
A distilled pathology foundation model backbone reduces computational requirements without sacrificing performance, enabling repeated analyses across larger patient cohorts.
These open models support population-scale discovery, helping researchers investigate disease biology, biomarkers, and clinical outcomes across diverse cancer datasets.
GigaPath (opens in new tab) and GigaTIME (opens in new tab) demonstrated how foundation models can support whole-slide analysis and tumor microenvironment modeling from routinely collected pathology data. GigaPath-Flash and GigaTIME-Flash make these capabilities substantially more efficient, enabling researchers to analyze larger cohorts, run more experiments, and move toward population-scale discovery.GigaPath-Flash and GigaTIME-Flash are research models. They are not intended or validated for clinical use, including diagnosis, prognosis, treatment selection, or other patient-care decisions. Performance may vary across datasets, scanners, institutions, populations, and use cases.
The scale opportunity in computational pathology
Histopathology is among the richest and most widely available sources of information in cancer research. Every tissue biopsy produces a whole-slide image that captures cellular morphology at subcellular resolution — and hospitals generate millions of these slides each year. This data contains information relevant to diagnosis, prognosis, treatment selection, and the biology of the tumor microenvironment.
Foundation models have begun to unlock this information at scale. But whole-slide images are large — often exceeding a gigapixel — and applying a foundation model to even a single slide requires processing thousands of image tiles. When a research question involves tens of thousands of patients, the computational cost grows quickly. And population-scale discovery is not a single model run: it requires repeated cycles of feature extraction, statistical analysis, hypothesis testing, and validation across patient subgroups, biomarkers, and clinical endpoints.
Computational cost limits the number of patients, datasets, tasks, and hypotheses that researchers can study. To realize the full potential of pathology foundation models, we need models that can be applied repeatedly and affordably across large patient populations.
From GigaPath and GigaTIME to the -Flash family
GigaPath (Nature, 2024) (opens in new tab) is a whole-slide foundation model pretrained on large-scale real-world histopathology data from Providence. Unlike models that operate only at the tile level, GigaPath learns contextualized representations of entire slides, capturing both local cellular patterns and global tissue architecture.
GigaTIME (Cell, 2026) (opens in new tab) extends this line of work to tumor microenvironments. Trained on 40 million cells with paired H&E and multiplex immunofluorescence (mIF) data, GigaTIME translates routine H&E images into virtual spatial proteomics maps across 21 protein channels. Applied to over 14,000 cancer patients, it generated a virtual population that uncovered more than 1,200 statistically significant associations between immune cell states and clinical biomarkers.
GigaPath and GigaTIME addressed the scale of pathology data and biological discovery. And now, the Flash family of models addresses scale of experimentation.
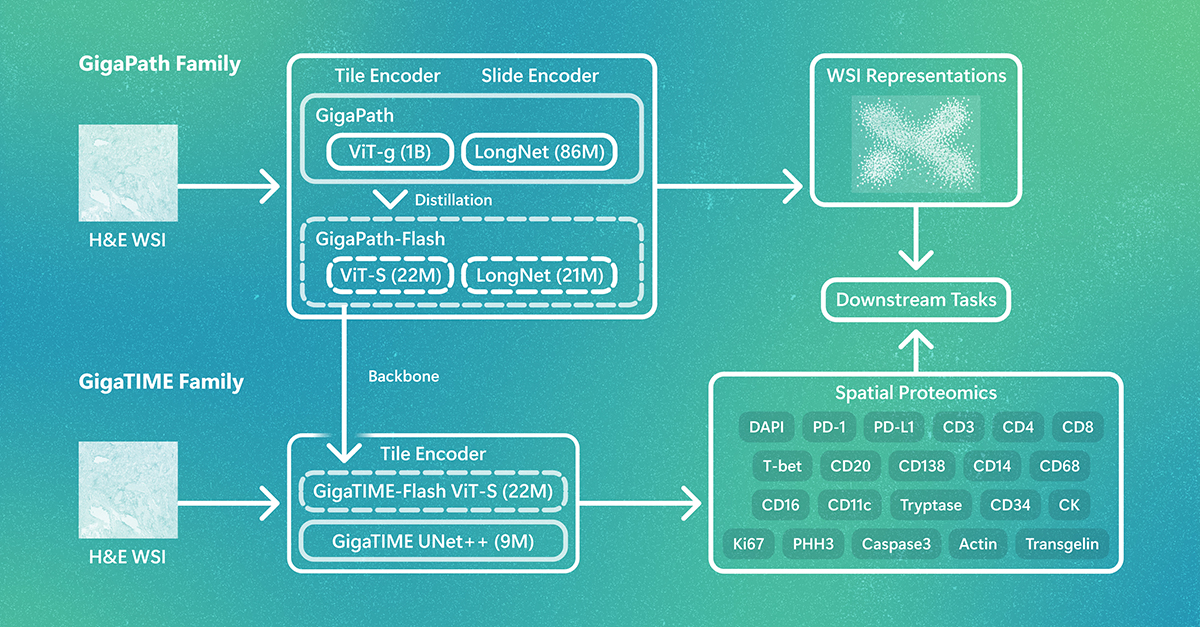
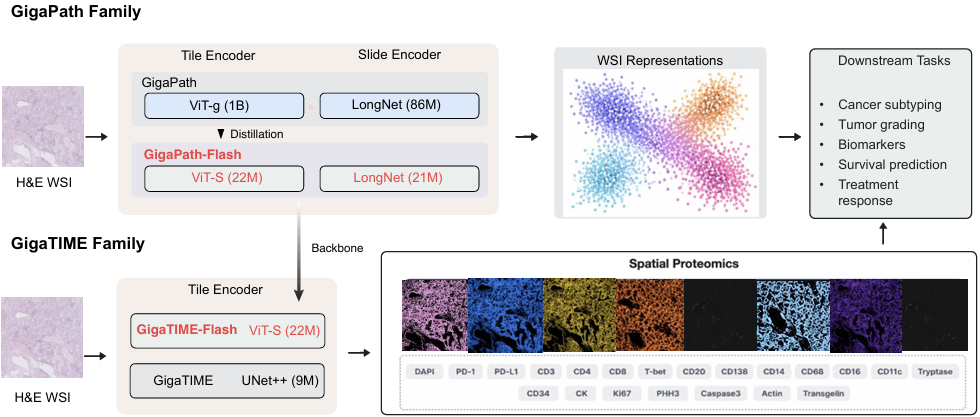
Figure 1: Overview of the GigaPath/GigaTIME model family. GigaPath-Flash provides efficient tile and slide encoders at 22M parameters. GigaTIME-Flash predicts spatial proteomics from H&E, replacing the CNN backbone with the distilled ViT-S encoder.
The Flash family shares a core design goal: preserving useful pathology representations while substantially reducing the computational resources required to generate and use them. Both models are built on a common efficient backbone — a compact ViT-S tile encoder distilled from the original billion-parameter GigaPath encoder — and both are released under the Apache 2.0 license.
GigaPath-Flash
GigaPath-Flash is an efficient foundation model for whole-slide representation learning. It combines a 22M-parameter ViT-S tile encoder with a 21M-parameter LongNet slide encoder. The tile encoder is distilled from the original GigaPath ViT-g teacher, transferring the representational capacity of a billion-parameter model into a backbone that is an order of magnitude smaller. The slide encoder contextualizes all tile embeddings via dilated attention, scaling linearly with the number of tiles.
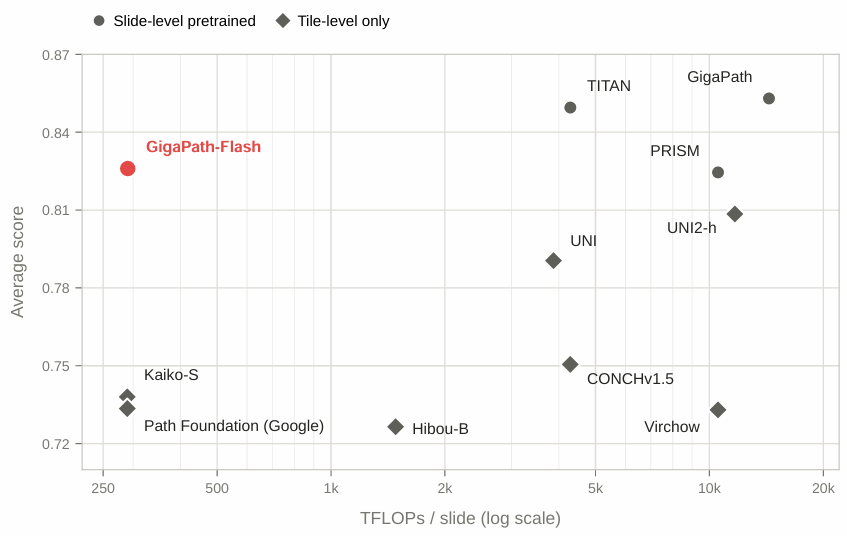
On slide-level classification benchmarks (PANDA prostate grading and EBRAINS brain tumor subtyping), GigaPath-Flash achieves the lowest inference cost among whole-slide pretrained models while retaining competitive performance — scoring within 3% of the original GigaPath at roughly 50 times less compute.
Figure 2: Efficiency–performance trade-off on whole-slide benchmarks. GigaPath-Flash (red, top-left) achieves competitive performance at substantially lower computational cost than other whole-slide pretrained models.
GigaTIME-Flash
GigaTIME-Flash replaces the CNN backbone of the original GigaTIME with the GigaPath-Flash ViT-S encoder, paired with a lightweight convolutional decoder for H&E-to-mIF translation. The model is fine-tuned using LoRA adapters, keeping the pretrained encoder weights largely frozen.
On both in-distribution and out-of-distribution cohorts spanning brain, breast, colon, and lung cancers, GigaTIME-Flash matches or improves upon the original GigaTIME in spatial protein prediction quality. The gains are particularly notable on out-of-distribution data, suggesting that the foundation model backbone improves generalization to previously unseen tissue types.
Figure 3: Mean windowed Pearson correlation for GigaTIME and GigaTIME-Flash on the GigaTIME test set and four out-of-distribution Prov-TMA cohorts. GigaTIME-Flash matches or improves upon the original across all cohorts.
Efficiency without giving up the foundation
The efficiency gains of the Flash models are substantial:
Model
Type
Efficiency gain
GigaPath-Flash
Whole-slide Foundation Model
~50× less compute, 97% of predictive performance compared to GigaPath
GigaTIME-Flash
Spatial Proteomics
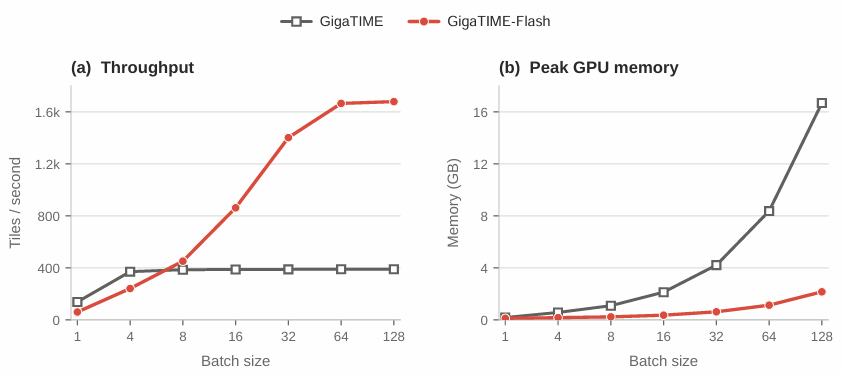
~6× faster, ~8× less memory, better predictive performance compared to GigaTIME
For a single slide, these differences reduce runtime and hardware requirements. Across tens of thousands of slides, they can determine whether an experiment is practical at all. To illustrate, we estimate the wall-clock time for generating virtual mIF across cohorts of different sizes on a single A100 GPU, assuming approximately 10,000 tiles per slide:
Model
1,000 slides
100K slides
1M slides
GigaTIME-Flash
~2 GPU-hours
~7 GPU-days
~70 GPU-days
GigaTIME
~7 GPU-hours
~30 GPU-days
~300 GPU-days
Estimates assume ~10,000 tiles per slide, batch size 128, single NVIDIA A100 GPU. Actual runtime depends on slide size, tiling resolution, and hardware.
Figure 4: GigaTIME efficiency scaling. Left: throughput (tiles/sec) vs. batch size. Right: peak GPU memory (GB) vs. batch size. GigaTIME-Flash scales to over 1,600 tiles/sec while using a fraction of the memory.
An open model release
Both GigaPath-Flash and GigaTIME-Flash are released as open-weight models under the Apache 2.0 license. Model weights and code are available on HuggingFace:
This is an early research release. Our current evaluations cover a limited set of benchmarks and cohorts, and broader validation across tasks, scanners, and patient populations is still needed. We expect the most valuable applications of these models to include scientific questions, cohorts, and use cases beyond those in our initial experiments. We welcome community evaluation, and we are equally interested in reports of where these models work well and where they fall short.
Downstream clinical applications will require additional multi-institutional and prospective validation.
Spotlight: Event Series
Microsoft Research Forum
Join us for a continuous exchange of ideas about research in the era of general AI. Watch the latest episodes on demand.
Efficiency as an enabler of discovery
GigaPath and GigaTIME demonstrated what pathology foundation models can learn from whole slides and tumor tissue. GigaPath-Flash and GigaTIME-Flash are a step toward making those capabilities usable across larger populations, more experiments, and a broader research community.
By making pathology foundation models more efficient, we hope to expand the scale of the scientific questions researchers can ask.
Acknowledgements
GigaPath-Flash and GigaTIME-Flash are joint work across Microsoft Research, the University of Washington, and Providence. For technical details, see the paper.
Paper co-authors: Naoto Usuyama, Jeya Maria Jose Valanarasu, Sicong Yao, Hanwen Xu, Jaspreet Bagga, Guanghui Qin, Robert E. Kramer, Cliff Wong, Soohee Lee, Hao Qiu, Theodore Zhengde Zhao, Racheli Ben Shimol, Angela Crabtree, Kevin Matlock, Eduardo Alejandro Lozano Garcia, Naiteek Sangani, Alberto Santamaria-Pang, Maximilian Rokuss, Yashna Hasija, Naisargi Manishkumar Patel, Jason Entenmann, Alexandra Q. Bartlett, Bill J. Wright, Bernard A. Fox, Brian Piening, Sheng Zhang, Sheng Wang, Tristan Naumann, Carlo Bifulco, Hoifung Poon
Skala 1.1 demonstrates the continuously improving nature of Microsoft Research’s deep-learning DFT approach: trained on 2.5× more data than its predecessor, it delivers substantially higher accuracy across key molecular simulation challenges, including thermochemistry, reaction kinetics, and molecular structure prediction.
Skala is now available in CP2K and is being integrated into Psi4, FHI-aims, ORCA and VASP, bringing next-generation DFT accuracy closer to the communities that rely on these codes every day.
Microsoft Research is also introducing a living benchmark that will track the computational performance of successive, increasingly optimized Skala releases to help the community measure and accelerate progress toward ever greater accuracy and efficiency.
Together, these developments mark another milestone toward a future in which computational chemistry simulations are both predictive and integrated in all relevant scientific and industrial workflows.
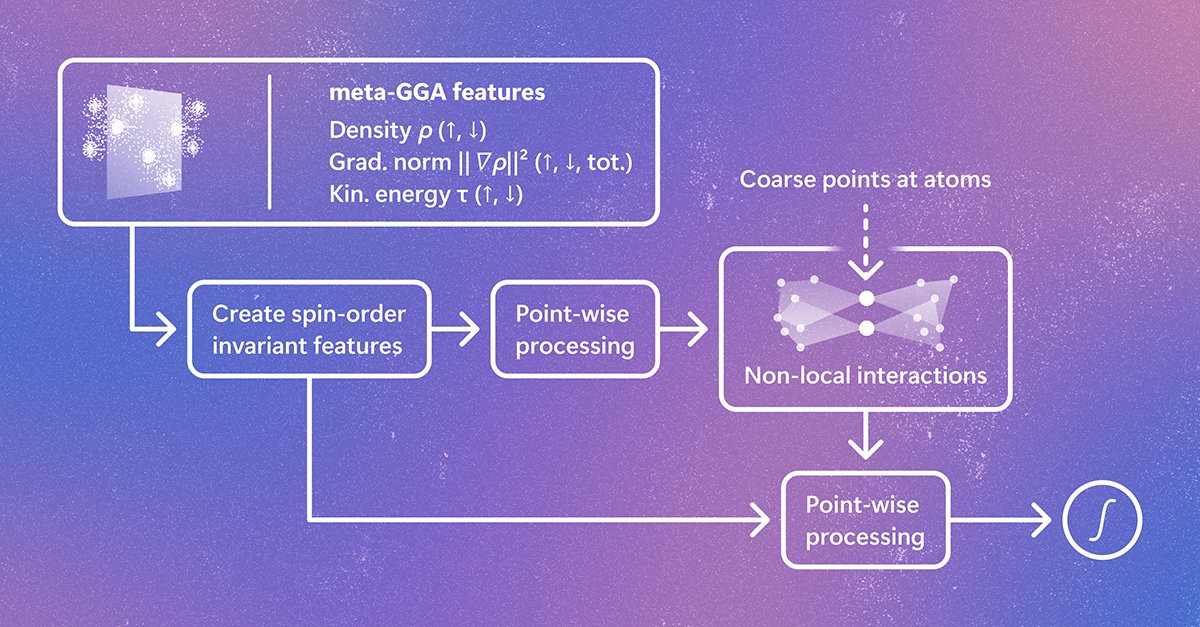
Bringing density functional theory (DFT) to predictive accuracy is a journey, not a single breakthrough. Since introducing Skala, our deep-learning exchange-correlation functional, we have continued to advance along two complementary fronts: improving accuracy and expanding accessibility across the computational chemistry ecosystem.
Figure 1: Accuracy of Skala-1.1 for thermochemistry, kinetics, and non-covalent interactions. At the computational cost of a meta-GGA functional, Skala 1.1 outperforms the best, most expensive global hybrid functionals, ranking first (earning gold medals) in 32 of the 55 categories of the widely used GMTKN55 benchmark, which spans a broad range of chemical problems.
On the accuracy front, the release of Skala-1.1 (opens in new tab) provides the first demonstration of the continuous-improvement paradigm underlying Skala. Trained on 2.5x more data than the first public version of Skala, the updated model delivers substantially improved performance across key challenges in molecular simulation, including main-group thermochemistry, reaction kinetics, and molecular structure prediction.
But accuracy alone is not enough. DFT is the computational engine behind a vast range of scientific and industrial workflows, spanning chemistry, materials science, catalysis, energy technologies, and drug discovery. To have real-world impact, advanced functionals must be accessible where scientists already perform their calculations. That is why we are also expanding the Skala ecosystem through collaborations with leading electronic-structure software developers.
Today, we are announcing that Skala is available in CP2K and is being integrated into Psi4, FHI-aims, ORCA and VASP, bringing next-generation DFT accuracy closer to the communities that rely on these codes every day. Alongside these integration efforts, we are introducing a living benchmark that tracks the computational performance of successive, increasingly optimized Skala releases. By providing a transparent and continuously updated reference for implementations across software packages and hardware platforms, this resource will help the community measure and accelerate progress toward ever greater accuracy and efficiency.
Together, these developments mark another milestone toward a future in which computational chemistry simulations are both predictive and accessible across a broader range of relevant scientific and industrial workflows.
Unlike the traditional “functional zoo”, where new functionals accumulate without replacing older ones, Skala follows a different philosophy: each release is designed to supersede the previous one. As new data, model architectures, and training strategies become available, the model improves while maintaining the same practical computational cost.
Skala-1.1 is the latest demonstration of this approach. It achieves a weighted average error of 2.8 kcal/mol on GMTKN55, a widely used benchmark suite comprising 55 categories of chemistry, including thermochemistry, reaction barriers, and noncovalent interactions. This level of accuracy surpasses today’s leading global (range-separated) hybrid functionals while retaining the efficiency of a semi-local functional. Beyond energies, Skala-1.1 also provides highly accurate electron densities, dipole moments, and molecular geometries.
These advances were enabled by major expansions of the Microsoft Research Accurate Chemistry Collection (opens in new tab) (MSR-ACC), our large-scale collection of high-accuracy quantum-chemistry reference data generated with expensive wavefunction methods. For Skala-1.1, we added new categories, including electron affinities and noncovalent clusters, increasing both the size and, crucially, the diversity of the training data. This data-driven approach allows Skala to improve systematically with each generation, moving us closer to a truly scalable and predictive DFT framework.
Available where scientists work
To fully realize the potential of Skala’s continuously evolving approach to DFT, we need dedicated infrastructure that allows new releases to be rapidly and seamlessly integrated into the major software packages used by scientists in industry and academia. In turn, this will establish the fast feedback loop essential for accelerating Skala’s ongoing development.
But no single software package can meet the needs of every application or research community. Computational chemistry and materials science rely on a rich ecosystem of electronic-structure codes, each shaped over decades to tackle specific scientific and industrial challenges. Bringing Skala to this broader ecosystem has therefore been a major focus of the past year. We are fortunate to build on the remarkable foundations created by the DFT community and grateful to the many researchers and developers who are helping to make Skala available within the software platforms that scientists use every day.
Spotlight: Event Series
Microsoft Research Forum
Join us for a continuous exchange of ideas about research in the era of general AI. Watch the latest episodes on demand.
In collaboration with the team of Prof. Thomas D. Kühne at the Center for Advanced Systems Understanding (CASUS) (opens in new tab), Skala has been successfully integrated into the open-source CP2K (opens in new tab) package. With more than 25 years of development, CP2K is a powerhouse for DFT simulations, particularly for large-scale systems and long-timescale molecular dynamics, while also providing a rich portfolio of high-accuracy electronic-structure methods. Skala expands the frontiers of what is possible within CP2K, delivering a step change in DFT accuracy while preserving the computational efficiency needed for simulations at scale. We are excited to see how CP2K’s scale and versatility, combined with Skala’s continuously improving accuracy, will enable new scientific applications and discoveries in the years ahead.
There is more to come. Together with its vibrant developer’s community , we are actively integrating Skala into the open-source Psi4 (opens in new tab) package, an essential platform for molecular electronic-structure research. Combined with the PySCF-based Skala Community Edition, this will make Skala available in three widely used open-source quantum chemistry packages.
Beyond open-source software, we are working closely with leading developers behind FHI-aims (opens in new tab), ORCA (opens in new tab), and VASP (opens in new tab), with the goal of making Skala broadly accessible across the major software platforms used in computational chemistry and materials science.
Validating accuracy across implementations: CP2K as case study
Thorough testing is essential for any new implementation. We want to ensure that Skala delivers consistent accuracy across different codes and computational settings. Together with the CP2K team, we developed a comprehensive suite of integration tests to verify that Skala produces numerically correct and reliable results. We are particularly grateful to the CASUS team, whose deep expertise in the numerical verification of computational methods was instrumental in designing and validating this testing framework.
Figure 2: Signed errors relative to high-accuracy reference values for a representative subset of GMTKN55, comparing the CP2K and PySCF implementations of Skala-1.1 using as closely matched numerical settings as possible. The two implementations agree to within 0.1 kcal/mol MAD across the entire subset.
Accuracy and broad availability only translate into scientific impact if Skala is also fast. Today, Skala can deliver performance comparable to semi-local meta-GGAs on both CPU’s (with an overhead that disappears for molecules with more than 20-30 atoms) and GPUs, and we are committed to preserving that efficiency as it is integrated across the electronic-structure software ecosystem.
But performance is not a fixed property. New Skala releases, improvements in libraries such as GauXC, and hardware-specific optimizations continuously improve efficiency and reveal new opportunities for further gains. Capturing this progress requires more than a single benchmark snapshot.
To provide a transparent and up-to-date view of Skala’s performance, we are publishing a benchmarking harness together with a living performance report (opens in new tab) that will be updated as new optimizations become available. This report tracks performance across a range of tasks and hardware platforms, while the harness enables package developers to benchmark, validate, and improve their own Skala implementations.
Figure 3: Computational cost of Skala on GPU and CPU, compared with a popular metaGGA functional (r2SCAN) and two hybrid functionals (B3LYP and M06-2X). On GPU, Skala 1.1 has the same cost as r2SCAN, and the hybrid functionals become more expensive for systems with more than ~1000 orbitals. On CPU, Skala has an overhead with respect to the other functionals for smaller systems, that disappears for systems with more than ~300 orbitals.
Acknowledgments
Skala is the product of a truly collaborative effort across AI for Science, and we thank our engineering, project management, and business operations teams for making this work possible. We also thank MSR Accelerator for their partnership in advancing data generation efforts and accelerating software integrations that help bring Skala to the broader scientific community.
MindTopo is a new benchmark for testing topological reasoning in AI, evaluating whether multimodal models can understand concepts such as connectivity, enclosure, order, separation, and knots.
The benchmark measures both reasoning and planning, testing not only whether models can recognize topological relationships in static images but also whether they can preserve and manipulate those relationships through a sequence of actions.
Current multimodal models perform much better on static recognition than interactive tasks, suggesting they struggle to maintain a consistent understanding of topology over time.
Failures often emerge during planning rather than perception, with models losing track of structural relationships as scenes change or proposing actions that violate physical constraints.
The findings highlight an important opportunity to advance AI systems for robotics and interactive environments, where understanding what stays connected, enclosed, ordered, or knotted is essential for reliable decision-making.
Can AI determine whether two rooms remain connected after a wall is added? Can it recognize whether an animal is inside a fence, distinguish a true knot from a tangled loop, or rearrange several ropes without allowing them to pass through one another?
These questions concern 3D topology, a form of spatial understanding based not on exact distances, angles, or shapes, but on structural relationships that persist as objects bend, stretch, or deform. Connectivity, enclosure, ordering, and knottedness are examples of topological properties. These properties are a foundational layer of human spatial understanding in Cognitive Science, yet they remain largely absent from how multimodal AI systems are evaluated.
In a new research study, we introduce MindTopo (opens in new tab), a benchmark designed to evaluate whether multimodal large language models possess this kind of topological intuition. Our findings reveal a substantial gap between recognizing topology in a static image and maintaining an innate understanding of that topology while planning and acting. Current models can sometimes identify a connected path, enclosed region, or knot in a single scene, but that understanding often breaks down once the model must manipulate the scene through a sequence of actions.
How MindTopo defines topological space
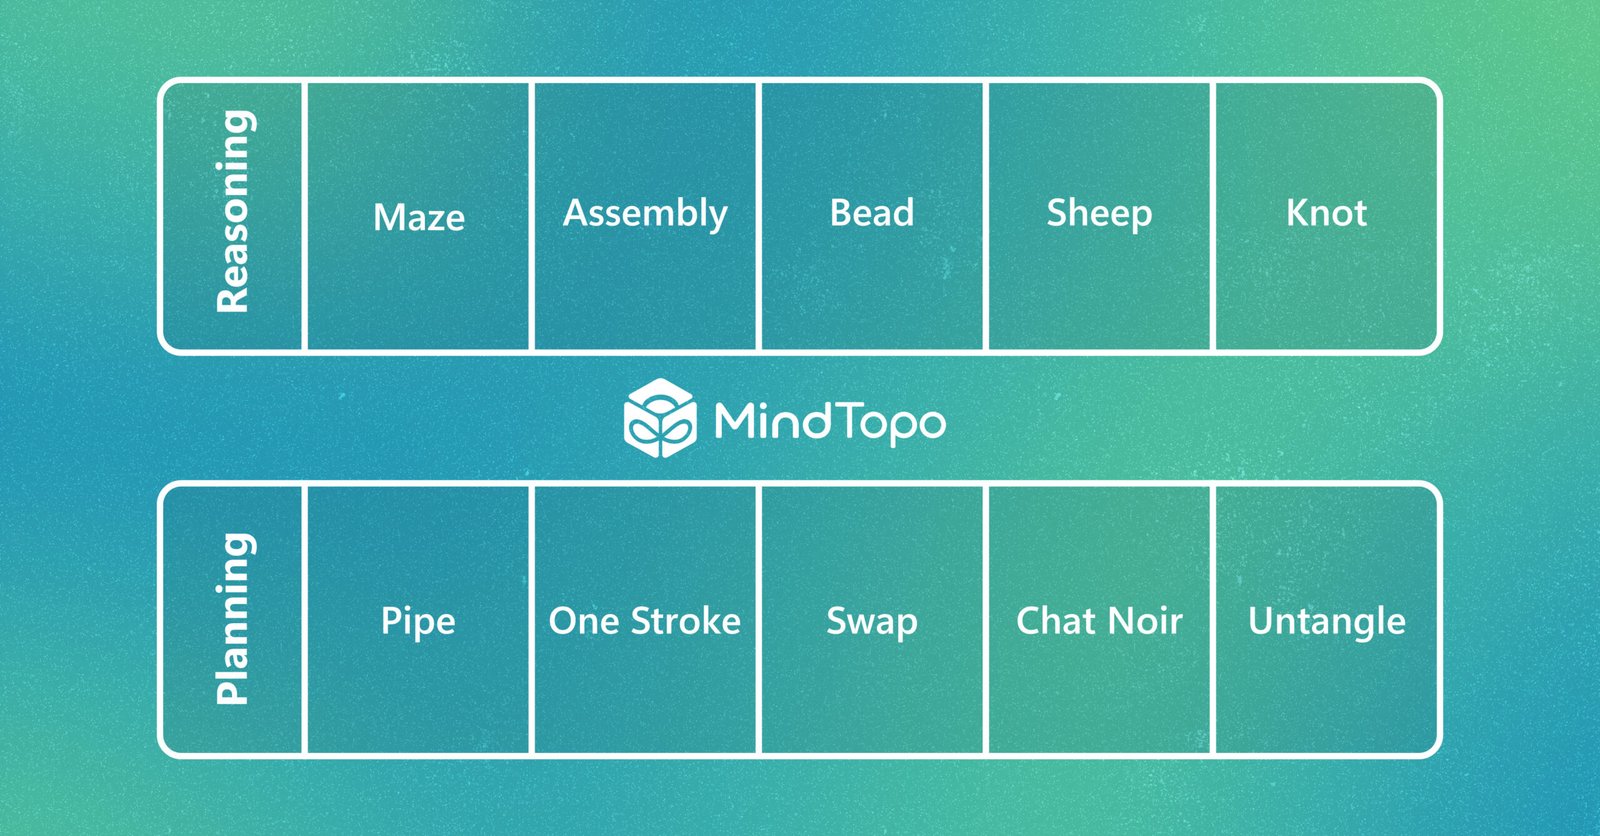
Most spatial evaluations for multimodal models focus on Euclidean properties such as distance, direction, size, and relative position. Inspired by Piaget and other cognitive literature’s classification of topological ability, MindTopo organizes its tasks around the following five categories:
Continuity asks whether a path or object remains unbroken.
Separation asks whether nearby elements form one structure or distinct parts.
Order tracks how elements are arranged along a path or through a transformation.
Enclosure tests whether a boundary creates an inside and an outside.
Knots tests whether ropes are truly knotted or linked rather than merely tangled in appearance.
Each category is evaluated at two cognitive levels. In reasoning tasks, a model examines one or more rendered scenes and answers a question about their topological structure: whether two points in a maze are connected, whether the sheep are inside the fence, whether a rope is truly knotted. In planning tasks, the model interacts with a simulated environment and selects actions that must create, preserve, or remove a particular relation, such as rotating pipe segments, drawing a separating path, rearranging blocks, trapping a moving agent, or untangling ropes. The environments enforce legal actions, so a model cannot solve a rope puzzle by passing one strand through another.
Figure 1. MindTopo pairs questions about static scenes with interactive tasks that require models to preserve or change the same topological relations.
All scenes are generated from controlled simulators, which provide exact ground truth and adjustable difficulty. That control makes it possible to separate two failure modes that otherwise look alike: a model that fails because a scene is visually complex, and a model that fails because it cannot maintain the underlying relationship as objects move.
Figure 2. MindTopo maps reasoning and planning tasks to continuity, separation, order, enclosure, and knots.
Seeing topology is not the same as acting on it
Across a broad set of proprietary and open-weight models, performance was consistently stronger on static reasoning than on interactive planning, and both remained well below human performance. The contrast was especially clear when success depended on preserving a relationship across many actions.
The error patterns help locate the problem. Static mistakes usually began with perception, such as missing a wall, opening, or crossing. Planning mistakes appeared after the scene had been understood. Models followed a locally plausible move without tracking its later consequences, lost the task over multiple turns, or proposed an action that violated the environment’s dynamics.
Spotlight: Microsoft research newsletter
Microsoft Research Newsletter
Stay connected to the research community at Microsoft.
We also tested whether image and video generation could help models maintain an understanding of topological relationships. Image generation sometimes helped when the relevant relation was visible in a single frame, but it remained unreliable across a sequence of crossings or moves. Video rollouts frequently altered topology or violated task dynamics. Visual simulation appeared useful only to the extent that it preserved structural constraints over time.
Building agents that preserve structure
MindTopo is intended as a controlled diagnostic for this gap. Robots, accessibility tools, and interactive assistants must understand not only where objects are, but also what remains connected, enclosed, ordered, or knotted as actions unfold. Closing that gap may require models that carry an explicit topological state, or world models whose predictions preserve topology by construction.