Author: admin

  • AlphaFold: Five years of impact

    AlphaFold: Five years of impact

    November 25, 2025 Science

    Demis Hassabis, John Jumper, Pushmeet Kohli and Anna Koivuniemi on behalf of the AlphaFold team

    Since 2020, AlphaFold has accelerated the pace of science and fueled a global wave of biological discovery — an achievement recognized with a Nobel Prize

    Five years ago, AlphaFold 2 solved the protein structure prediction problem, unlocking new avenues of biological research and providing our first major proof point that AI can be a powerful tool to advance science.

    Proteins are the complex, microscopic machines that drive every process in a living cell. Composed of long, unique chains of amino acids, they precisely fold into a 3D structure that largely defines the protein’s function – making knowledge of this shape critical for drug discovery and understanding disease.

    p53 is a cellular tumor antigen related to diseases such as cancer. It is one of the most popular proteins in the AlphaFold Protein Database.

    If a protein misfolds, it can lose its function and lead to disease, like Alzheimer’s and Parkinson’s. For decades, determining these structures was a monumental task, often taking a year or more of expensive, painstaking experimental work.

    At the CASP 14 (Critical Assessment of protein Structure Prediction) competition in 2020, AlphaFold 2 predicted the structures of proteins based just on their amino acid sequences with astonishing accuracy – an achievement widely hailed as a solution to this 50-year-old grand challenge in biology. But the true, lasting impact of this breakthrough came when we put AlphaFold in the hands of the research community.

    A global engine for discovery

    In 2021, we launched the AlphaFold Protein Database in partnership with EMBL-EBI, which was a tipping point toward AlphaFold becoming a scientific tool adopted around the world. And one year later, we released AlphaFold 2’s predictions for more than 200 million protein structures, achieving what would take hundreds of millions of years to solve experimentally.

    The freely available AlphaFold Protein Database has accelerated science on a scale that was previously unimaginable. It has been used by over 3 million researchers in more than 190 countries, including over 1 million users in low- and middle-income countries. Over 30% of AlphaFold-related research is focused on better understanding disease, benefiting human welfare.

    The profound scientific and societal value of this work was recognized in 2024 with the Nobel Prize in Chemistry.

    For half a century, scientists struggled to predict how proteins fold. A puzzle at the heart of understanding life and curing disease. Then, five years ago, the AlphaFold team cracked the code.

    Real-world transformation

    AlphaFold has become a standard tool for scientists tackling some of the world’s most pressing issues, from conservation to heart health.

    Breeding healthier and stronger honeybees

    Scientists in Europe used AlphaFold to understand a key immunity protein in honeybees, Vitellogenin (Vg). These structural insights are now being applied to conservation efforts for endangered bee populations and guiding the development of AI-assisted breeding programs for healthier, more resilient pollinators.

    Revealing a key protein behind heart disease

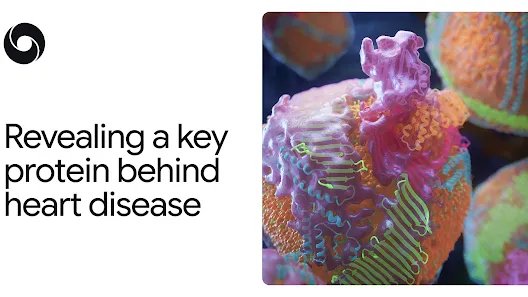
    Atherosclerosis, caused by “bad cholesterol” (LDL), is the leading cause of global mortality. For decades, the structure of the central protein in LDL, apolipoprotein B100 (apoB100), remained elusive. AlphaFold 2 helped finally reveal its complex, cage-like shape. This long-awaited blueprint gives pharmaceutical researchers the atomic-level detail needed to design new preventative heart therapies.

    Revolutionizing Research

    AlphaFold is also transforming scientific research – broadening access, accelerating timelines and dramatically lowering the cost.

    Expanding access

    Turkish undergraduate students Alper and Taner Karagöl taught themselves structural biology during the pandemic using online AlphaFold tutorials – with no prior training. They’ve now published 15 research papers.

    This picture shows a water-soluble version of the EAAT1 protein. EAAT1 is a transporter in brain cells that normally sits in the membrane and helps clear the neurotransmitter glutamate. Here, the protein has been redesigned using the QTY method, which swaps water-repelling amino acids with water-friendly ones so it can dissolve in water. The blue coils are the protein, and the surrounding dots are water molecules and salt ions.

    Increasing speed of discovery

    Cyril Zipfel, professor of Molecular & Cellular Plant Physiology at the University of Zurich and Sainsbury Lab, saw research timelines shrink drastically. They used AlphaFold alongside comparative genomics to better understand how plants perceive changes in their environment, paving the way for more resilient crops.

    AlphaFold has been cited in more than 35,000 papers and more than 200,000 papers incorporated elements of AlphaFold 2 in their methodology. It’s also enhancing the quality of work being produced.

    An independent analysis of AlphaFold 2’s impact, carried out by the Innovation Growth Lab, suggests that researchers using AlphaFold 2 see an increase of over 40% in their submission of novel experimental protein structures. Those protein structures are more likely to be dissimilar to known structures, encouraging the exploration of uncharted areas of science. Also, research linked to AlphaFold 2 is twice as likely to be cited in clinical articles, and is significantly more likely to be cited by a patent, than typical works in structural biology.

    A new era of digital biology

    One of the most exciting examples of AlphaFold’s impact is Isomorphic Labs – an AI drug discovery company founded in 2021 when the breakthrough model proved to be powerful enough to be applied to rational drug design. Isomorphic Labs has since developed a unified drug design engine to dramatically change how it designs new medicines and speed up scientific discovery with an ambition to one day solve all diseases.

    Together with Isomorphic Labs, we developed AlphaFold 3, which offers an unprecedented view into cells that we expect to drive a transformation of the drug discovery process and usher in an era of “digital biology.”

    The model is designed to predict the structure and interactions of all of life’s molecules — not just proteins, but DNA, RNA, and ligands (the small molecules that make up most drugs). It can also generate the joint 3D structures of entire molecular complexes, allowing a holistic view of how a potential drug molecule binds to its target protein, or how proteins interact with genetic material.

    The AlphaFold Server is empowering non-commercial researchers globally to harness this technology, accelerating their ability to formulate and test new hypotheses. So far, it’s helped make more than 8 million folds – predictions of structures and interactions – for thousands of researchers around the world.

    John Jumper, one of the most instrumental scientists behind AlphaFold shares stories about his Nobel win, the tool’s unexpected applications, and the shift in architecture from AlphaFold 2 to the more comprehensive AlphaFold 3.

    The future of AI for science

    Inspired by AlphaFold, we’ve developed a new generation of models to solve problems across biology. AlphaMissense and AlphaGenome use AI to assess the genetic mutations that underpin disease. Our AlphaProteo model can design novel, high-strength protein binders that target diverse molecules – including those associated with cancer and diabetes. These models are deepening our understanding of complex diseases and ultimately driving the development of new treatments.

    Biology was our first frontier, but we view AlphaFold as the template for how AI can accelerate all of science to digital speed. From fusion and Earth sciences to scientific discovery as a whole, we’re pursuing the next AlphaFold-like breakthroughs. We’re excited to continue partnering with the global scientific community, empowering researchers everywhere to tackle the biggest challenges facing humanity.
    AlphaGenome: AI for better understanding the genome

    AlphaProteo generates novel proteins for biology and health research

    A glimpse of the next generation of AlphaFold

    A catalogue of genetic mutations to help pinpoint the cause of diseases

    AlphaFold reveals the structure of the protein universe

    AlphaFold: a solution to a 50-year-old grand challenge in biology

  • Revealing a key protein behind heart disease

    Revealing a key protein behind heart disease

    November 25, 2025 Science

    In a breakthrough powered by AlphaFold, scientists have mapped the structure of the large protein that gives “bad cholesterol” its form – a discovery that could help transform how researchers and clinicians treat the world’s leading cause of death

    The race to reveal a key protein behind heart disease has long been both an important public health goal and a stubborn scientific problem.

    For assistant professors Zachary Berndsen and Keith Cassidy at the University of Missouri (Mizzou), it was also personal. Both have a family history of heart disease – a reminder of what’s at stake in their work to better understand and ultimately help treat this deadly condition.

    “For 50 years, people have wanted to see what this protein looked like,” says Berndsen.

    That protein, apoB100, has defied mapping not only because it’s enormous (for a protein), but also because it connects to fats and other molecules in complicated ways. ApoB100 forms the molecular scaffold of “bad cholesterol”, which is known to scientists as low-density lipoprotein (LDL).

    LDL is the major carrier of fat through the bloodstream and a key risk factor for atherosclerotic cardiovascular disease (ASCVD), the world’s leading cause of death. Discovering the structure of its key protein promised to shed light on how bad cholesterol becomes harmful inside the body, giving scientists a better chance to develop ways to prevent and treat ASCVD. AlphaFold is playing a central role in this effort.

    At Mizzou, biochemist Berndsen first used cryo-electron microscopy (cryo-EM) to capture images of LDL particles. The images weren’t sharp enough to map the structure of apoB100 with atomic precision, so Berndsen’s physicist collaborator, Cassidy, turned to AlphaFold. He used it to generate atomic-resolution predictions of the protein’s structure and then refined those predicted shapes by comparing them against the cryo-EM image data.

    Coming at the problem using both cryo-EM microscopy and Alphafold is what unlocked this breakthrough, says Cassidy: “AlphaFold played a profound role in this discovery, providing the raw material to interpret our experimental structure in a way that was frankly impossible before.”

    The resulting model revealed bad cholesterol’s key protein in remarkable detail: a cage-like shell that wraps around each LDL particle, including a ribbon-like belt that keeps the particle intact in the bloodstream. Knowing this structure opens new possibilities for preventing, diagnosing and treating high cholesterol and ASCVD, including therapies that could target LDL more precisely. The potential benefit to global health is hard to overstate.

    While such applications will take time, revealing the structure of apoB100 is a landmark achievement, and a deeply satisfying one for Berndsen. “It was the first structure I ran through AlphaFold the week it became available, and the first protein I wanted to look at with our two-storey cryo-EM machine,” he says. “Solving the structure of apoB100 was a dream come true.”

  • Google DeepMind supports U.S. Department of Energy on Genesis: a national mission to accelerate innovation and scientific discovery

    Google DeepMind supports U.S. Department of Energy on Genesis: a national mission to accelerate innovation and scientific discovery

    December 18, 2025 Science

    Pushmeet Kohli and Tom Lue

    We stand at an inflection point where the convergence of advanced AI and scientific research promises to unlock a new golden age of discovery. Recognizing this, we’re pleased to support the White House’s Genesis Mission – a historic national effort to use AI to transform how scientific research is conducted and accelerate the speed of American science. The Genesis Mission will mobilize the U.S. Department of Energy’s (DOE) 17 National Laboratories, industry and academia to build an integrated discovery platform, accelerating breakthroughs across the nation’s most pressing challenges including energy, scientific discovery, and national security.

    At Google DeepMind, our mission is to build AI responsibly to benefit humanity. There is perhaps no clearer expression of this than the application of AI within science. Scientists today face significant obstacles of unprecedented scale and complexity — from shaping and simulating the intricate dynamics of fusion plasma, to exploring the vast search space of new materials, and finding a way to process and understand ever-growing volumes of data and literature. Modern deep learning methods are uniquely suited to address these challenges and compress the time new discoveries would otherwise require.
    To help realize the ambitious vision in the Genesis Mission, Google and the DOE are partnering to support the Administration’s goal of harnessing the AI and advanced computing revolution to dramatically expand the productivity and impact of American research and innovation within a decade. We see this as the beginning of an enduring partnership in AI for Science that we will look to grow and expand in the months and years ahead.

    Putting our advanced AI tools into the hands of American scientists

    Google DeepMind will provide an accelerated access program for scientists at all 17 DOE National Laboratories to our frontier AI for Science models and agentic tools, starting today with AI co-scientist on Google Cloud. AI co-scientist is a multi-agent virtual scientific collaborator built on Gemini, which is trained on Google’s world class TPUs. This system is designed to help scientists synthesize vast amounts of information to generate novel hypotheses and research proposals, and accelerate the pace of scientific and biomedical discoveries.

    AI co-scientist is already showing its potential across diverse biomedical applications. It proposed novel drug repurposing candidates for liver fibrosis that were validated through laboratory experiments and predicted complex antimicrobial resistance mechanisms that matched experiments before they were even published, demonstrating the potential to accelerate hypothesis development from years to days. It’s also showing early promise in additional fields like physics, chemistry, computer science, and more.

    In early 2026, we will expand our accelerated access program for National Laboratories to include:

    • AlphaEvolve – a Gemini-powered coding agent for designing advanced algorithms that is showing incredible promise for application across many areas in computing and math and, we believe, could be transformative across many more areas such as material science, drug discovery and energy. For example, AlphaEvolve enhanced the efficiency of Google’s data centers, chip design and AI training processes — including training the large language models underlying AlphaEvolve itself.
    • AlphaGenome – an AI model to help scientists better understand the non-coding part of DNA, speeding up research on genome biology and improving disease understanding. With more data on plant genomes, AlphaGenome could potentially be extended to help improve crop resistance and other applications including sustainable biofuels and advanced biomaterials.
    • WeatherNext – a state-of-the-art family of weather forecasting models. Our partnership with the U.S. National Hurricane Center already supports their cyclone forecasts and warnings, helping communities prepare for disasters earlier.

    DOE and all National Laboratories can also access Gemini for Government, which brings together the best of Google’s AI-optimized and accredited commercial cloud with our industry-leading Gemini models – including our most intelligent model Gemini 3 with state-of-the-art reasoning capabilities and multimodal understanding.

    We’re excited to see what America’s leading researchers will be able to do with our frontier AI models and agentic tools.

    A history of collaboration for scientific progress

    We’ve seen what’s possible when industry-leading technology can build upon the work of the National Laboratories. The foundational work by DOE’s Brookhaven National Laboratory on the Protein Data Bank was crucial for the development of AlphaFold, our AI system that can predict the 3D structure of proteins, the development of which was recognized through Demis Hassabis and John Jumper’s co-award of the 2024 Nobel Prize in Chemistry. The AlphaFold Protein Database has now been used by more than three million scientists in over 190 countries to accelerate research, from effective malaria vaccines to groundbreaking gene therapies.

    Looking ahead

    Through the Genesis Mission, we’ll be accelerating American scientific leadership by also exploring research collaborations with National Laboratories in areas including fusion energy, new materials discovery and earth science.

    The challenges facing our world—from energy to disease to security—demand unprecedented scientific innovation. By combining human ingenuity with advanced AI capabilities, we believe we can help America’s scientists achieve discoveries that would have seemed impossible just years ago.

  • How we’re bringing AI image verification to the Gemini app

    How we’re bringing AI image verification to the Gemini app

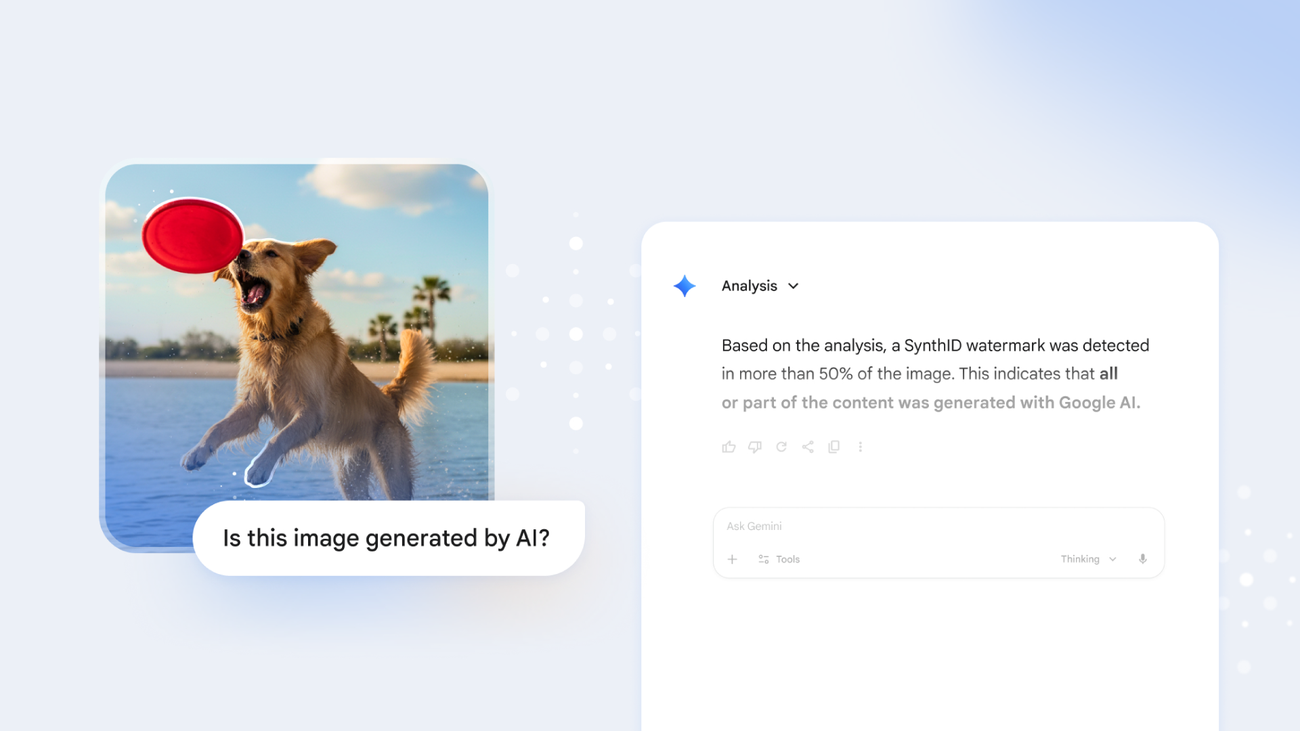
    We are increasing content transparency by introducing the ability to verify if an image was generated or edited by Google AI right in the Gemini app.


    Golden retriever catching frisbee over water. UI overlay shows Google AI watermark detected.

    At Google, we’ve long invested in ways to provide you with helpful context about information you see online. Now, as generative media becomes increasingly prevalent and high-fidelity, we are deploying tools to help you more easily determine whether the content you’re interacting with was created or edited using AI.

    Starting today, we’re making it easier for everyone to verify if an image was generated with or edited by Google AI right in the Gemini app, using SynthID, our digital watermarking technology that embeds imperceptible signals into AI-generated content.

    We introduced SynthID in 2023. Since then, over 20 billion AI-generated pieces of content have been watermarked using SynthID, and we have been testing our SynthID Detector, a verification portal, with journalists and media professionals.

    How it works

    If you see an image and want to confirm it has been made by Google AI, upload it to the Gemini app and ask a question such as: “Was this created with Google AI?” or “Is this AI-generated?”

    Gemini will check for the SynthID watermark and use its own reasoning to return a response that gives you more context about the content you encounter online.

    What’s next

    This launch builds on our history of providing context about images in Google Search and exploring new research innovations like Backstory from Google DeepMind. Looking ahead, we will continue to invest in more ways to empower you to determine the origin and history of content online. Soon, we’ll expand SynthID verification to support additional formats beyond images, such as video and audio, and bring these capabilities to more surfaces, such as Search.

    In addition to our own tools, we are collaborating with industry partners to advance content transparency and authenticity standards across our product ecosystem — including YouTube, Search, Pixel and Photos — through our role on the steering committee of the Coalition for Content Provenance and Authenticity (C2PA).

    As part of this, rolling out this week, images generated by Nano Banana Pro (Gemini 3 Pro Image) in the Gemini app, Vertex AI and Google Ads will have C2PA metadata embedded, providing further transparency into how these images were created. We look forward to expanding this capability to more products and surfaces in the coming months.

    Over time, we will also extend our verification approach to support C2PA content credentials, meaning you’ll be able to check the original source of content created by models and products that exist outside of Google’s ecosystem.

    This work is central to our commitment to bold and responsible AI. We look forward to further contributing to the future of AI transparency.

    Related stories

  • Build with Nano Banana Pro, our Gemini 3 Pro Image model

    Build with Nano Banana Pro, our Gemini 3 Pro Image model

    Here’s how developers can use Nano Banana Pro (Gemini 3 Pro Image), a powerful new image generation and editing model with advanced features and creative control.


    Alisa Fortin

    Product Manager, Google DeepMind

    Naina Raisinghani

    Product Manager, Google DeepMind


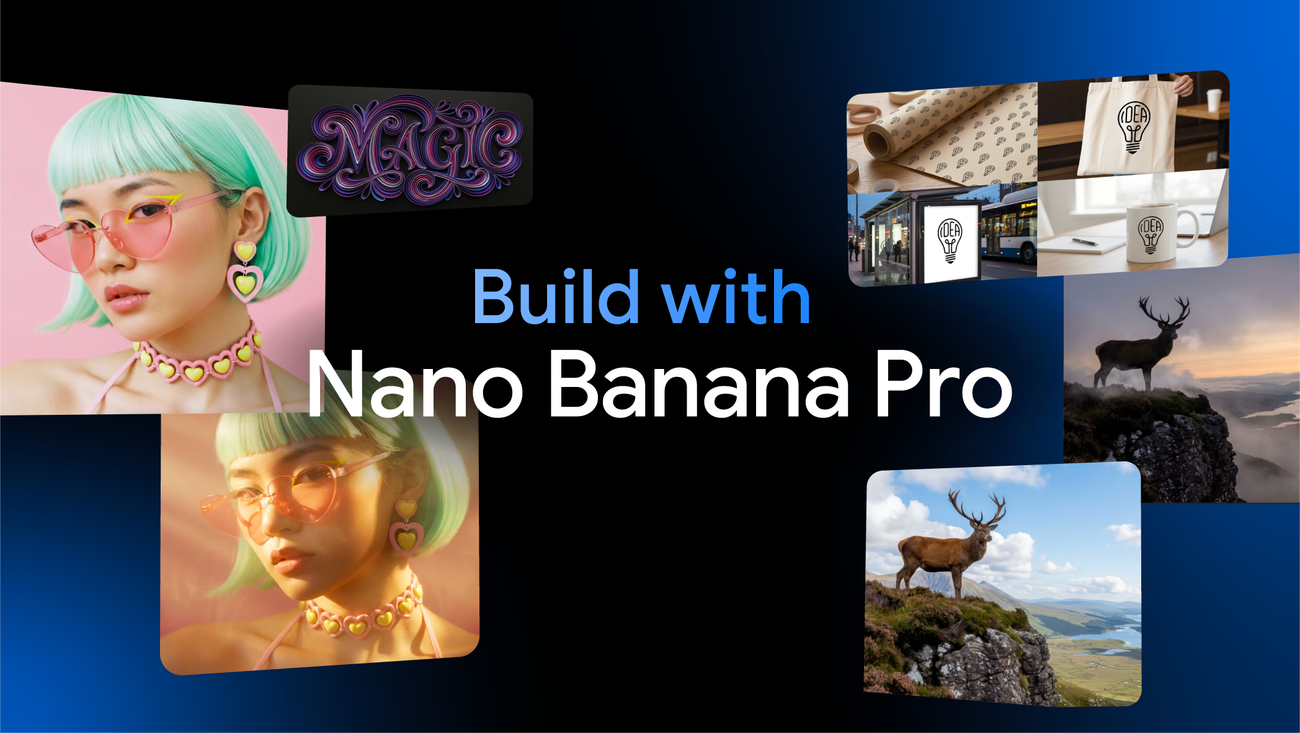
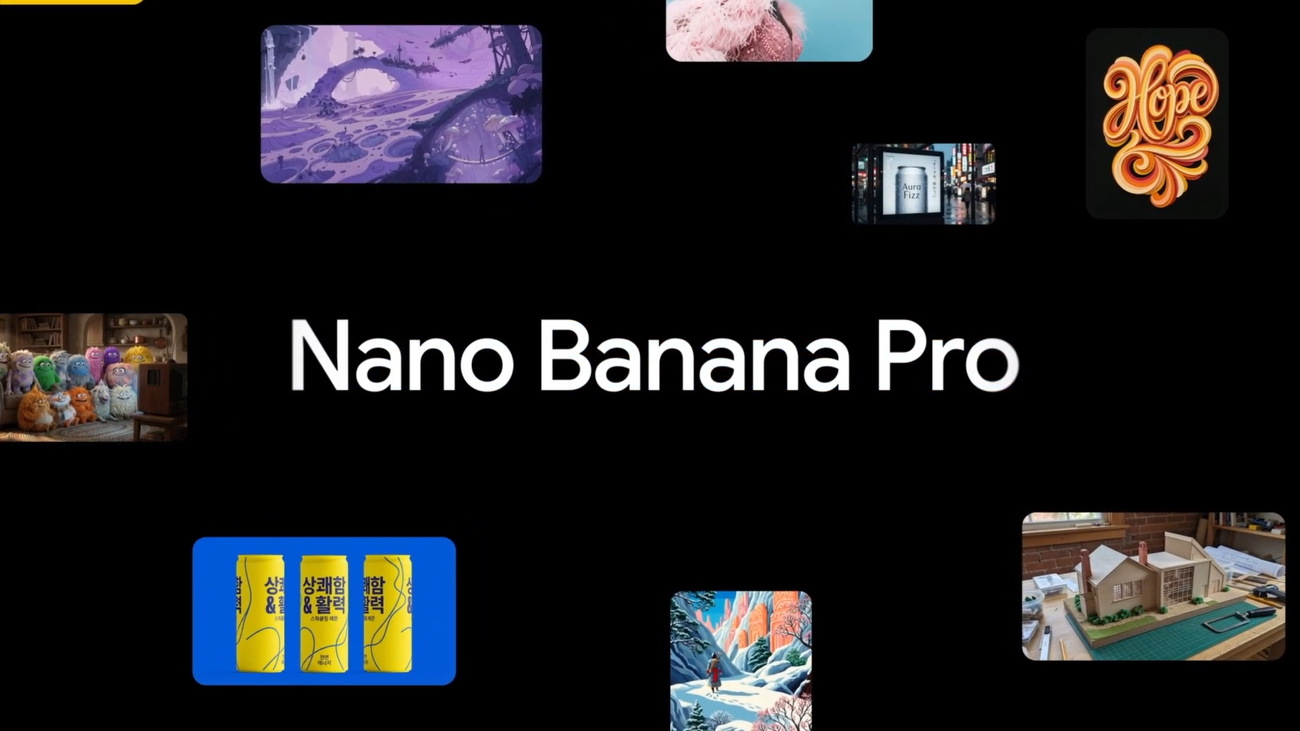
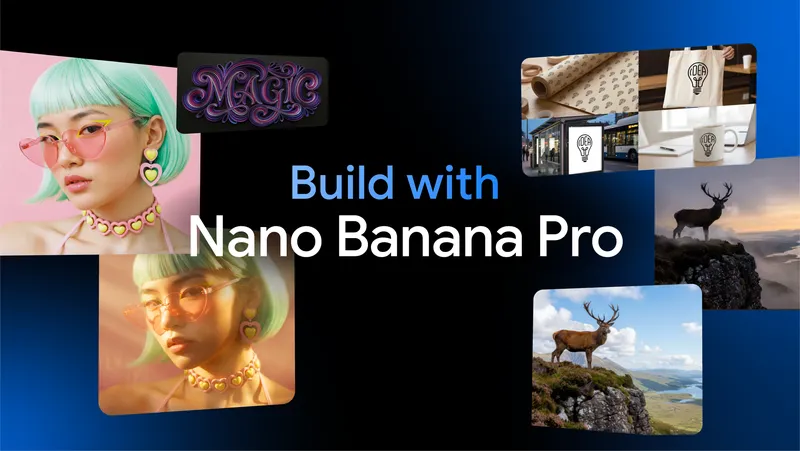
    Image with multiple input-output images with the text Build with Nano Banana Pro in the center

    Today, we’re releasing Nano Banana Pro (Gemini 3 Pro Image), a higher-fidelity model built on Gemini 3 Pro for developers to access studio-quality image generation. This follows our release of Nano Banana (Gemini 2.5 Flash Image) just a few months ago. Since then, we’ve loved seeing the community put its key features to work — from character consistency to photo restoration, and even using its capabilities to make local edits in an infinite canvas.

    This state-of-the-art image generation and editing model is starting to roll out in paid preview to build a new wave of intelligent, multimodal applications with the Gemini API in Google AI Studio and Vertex AI for enterprises. This model unlocks high-fidelity images with higher accuracy in text rendering and robust world knowledge, supercharged by the model’s ability to use grounding with Google Search to retrieve data based on the user’s prompt.

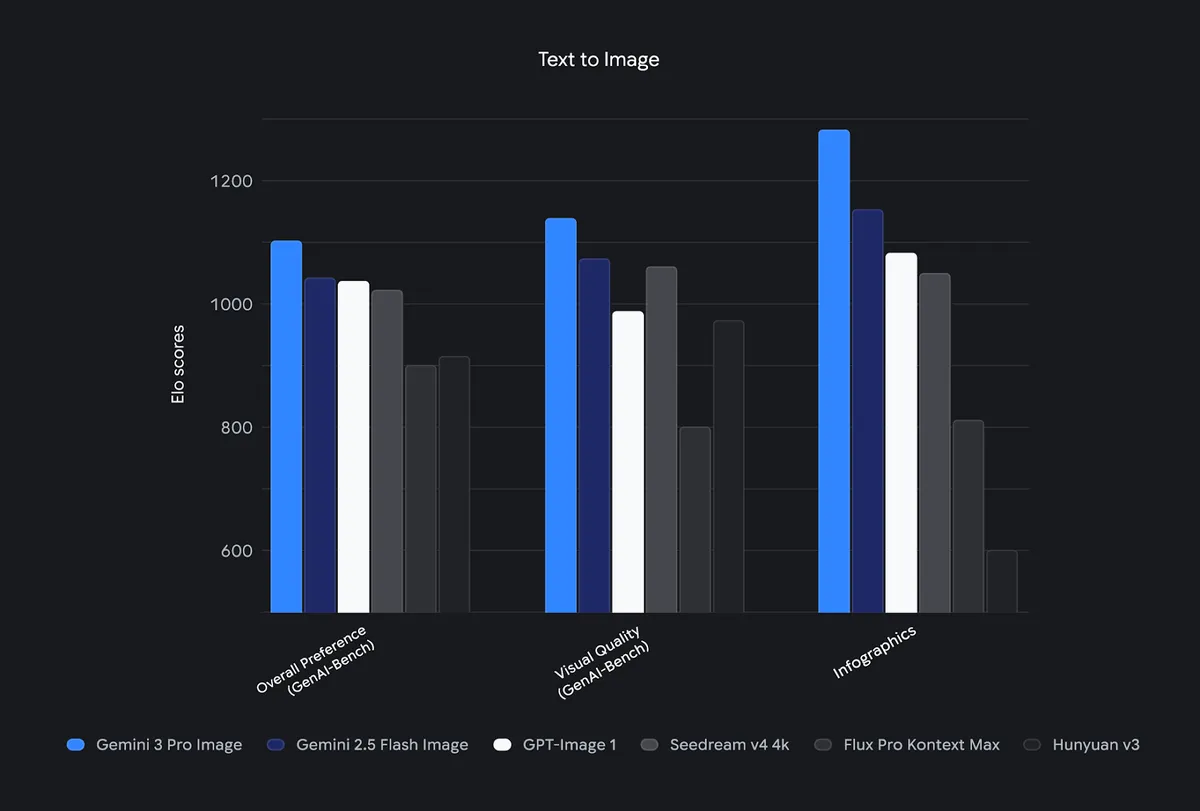
    Gemini 3 Pro Image excels on Text to Image AI benchmarks.

    Gemini 3 Pro Image Text to Image AI benchmark bar chart compared to other leading competitors

    We are also expanding the reach of Gemini 3 Pro Image across the developer ecosystem. In Google Antigravity — our new agentic development platform — coding agents can now directly leverage these image generation capabilities to generate detailed UI mockups for user review or even new visual assets before implementing in code. Additionally, leading creative platforms are integrating the model, including Adobe and Figma.

    High fidelity and controls

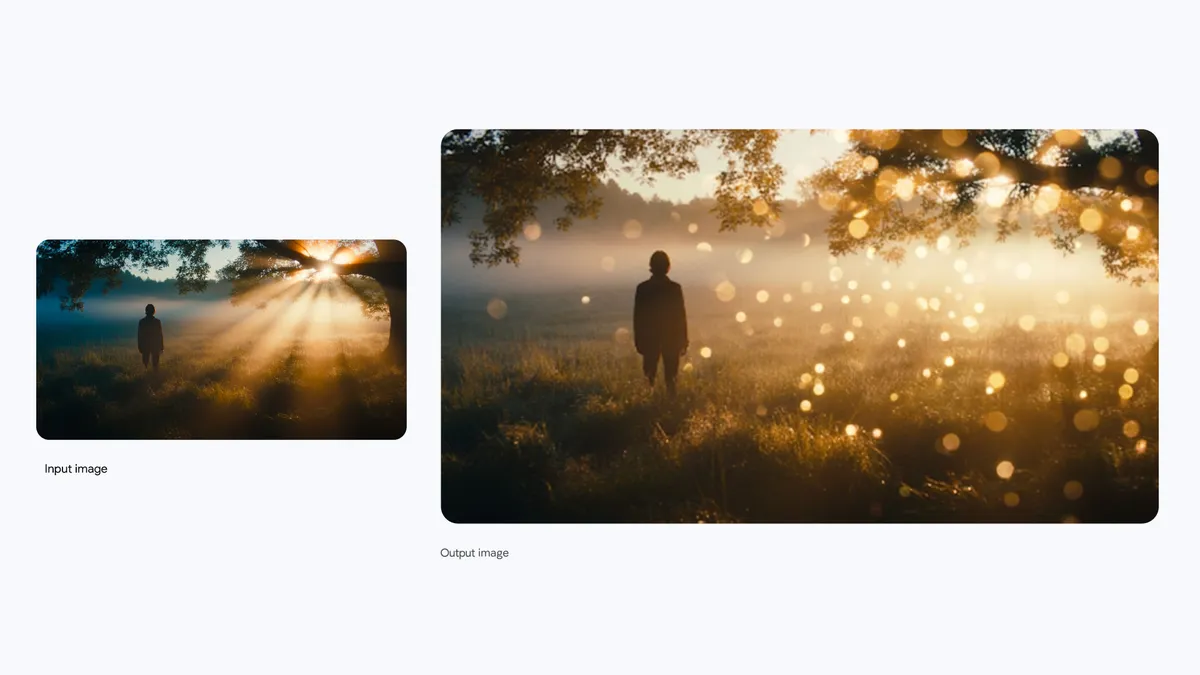
    If you’re building advanced tools that require precision, Gemini 3 Pro Image gives you control over the physics (lighting, camera, focus, color grading) and composition of the image to ensure professional-quality outputs.

    A silhouette lost in a sea of golden bokeh and morning mist.

    Prompt: Replace volumetric lighting with bokeh

    Image showing a side by side of an input image of the silhouette of a man with scattered sun rays and an output image where the same image with more volumetric lighting using AI

    With 2K and 4k resolution available, you can ensure outputs meet resolution standards required for professional production. Effortlessly create cohesive advertisements by combining diverse elements such as product images, logos, and references. Achieve consistent resemblance for up to five individuals, integrate six high-fidelity shots, or blend as many as fourteen standard inputs into a single, polished ad. Try our demo app that allows you to pair logos with products to create your own mockup designs.

    Demo app that brings product design to life with reference images. Sequences shortened.

    Improved text rendering and localization

    Gemini 3 Pro Image offers a significant leap forward from 2.5 Flash Image, transforming abstract image generation into functional assets. It excels in handling logic and language, and delivers state-of-the-art text rendering, producing clear, accurate text integrated in your images.

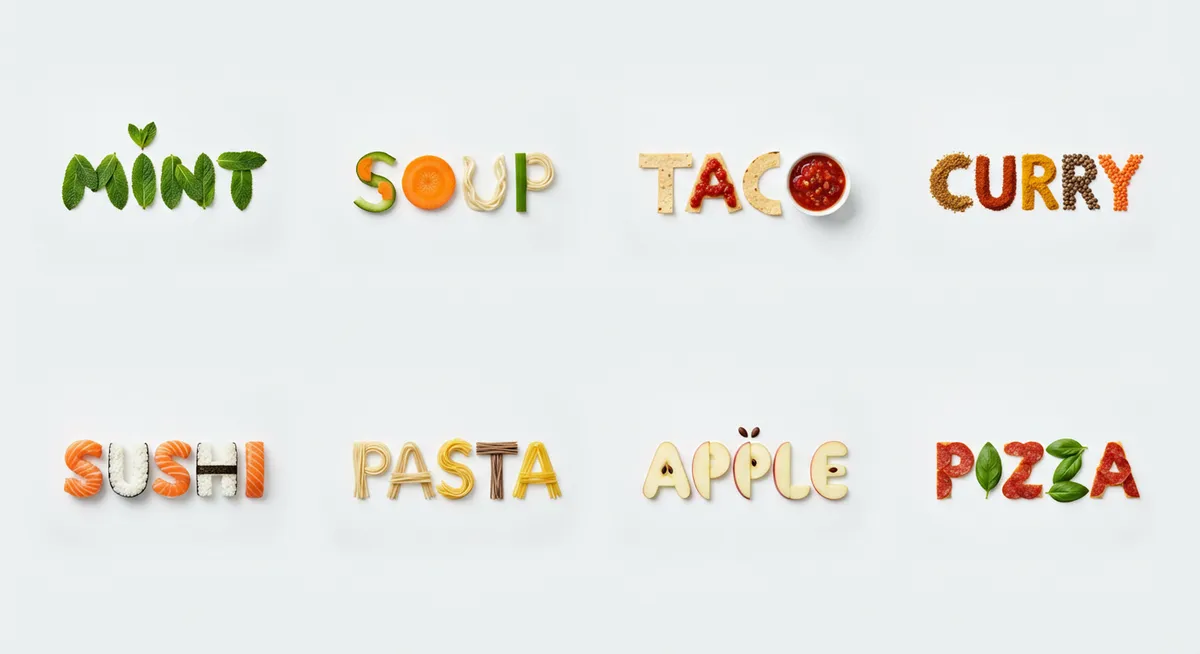
    Creative food photography where each word is artistically spelled out using the actual ingredients associated with that food.

    Prompt: Make 8 sophisticated minimalistic logos, each is a fun food word, and make letters from realistic food to express the meaning of this word. composition: a rendering of all logos on a single solid white background

    Image showing the words Mint, soup, taco, curry, sushi, pasta, apple and pizza rendered using food items with AI

    It’s also an ideal solution for developing marketing collateral, educational content and numerous other applications. Try the model’s capabilities in our comic book generator app in Google AI Studio, where you can create original multi-page comic books featuring you and a friend, complete with advanced text rendering and stylization.

    Demo app that creates a comic book in your chosen language based on photos and selected genre. Sequences shortened.

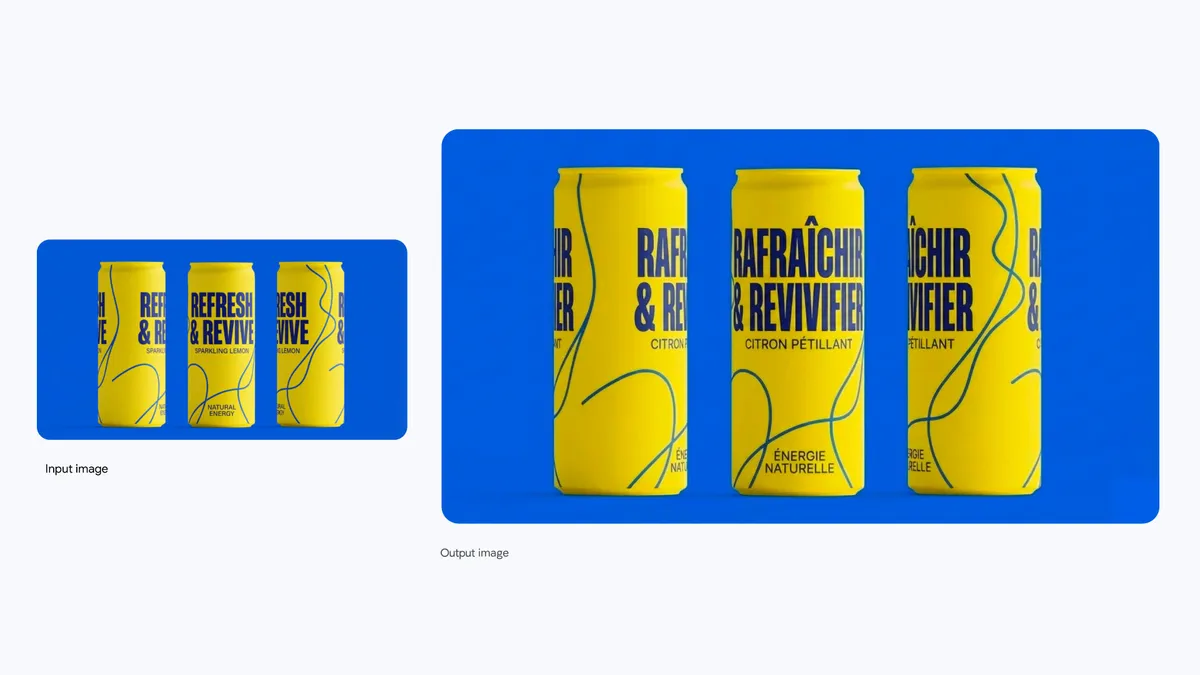
    With Gemini 3 Pro Image, we’ve removed the barrier between image generation and localization logic. This advanced model grasps the semantic context of an image, enabling effortless language changes on elements like menus, signs, or documents utilizing image-to-image generation keeping original artistic style or layout.

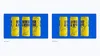
    A beverage campaign concept showcasing accurate translation and rendering of English text into French.

    Prompt: Translate to French

    Side by side of an input image of a set of cans with text and output image with text on can translated in French using AI

    Access to the world’s knowledge

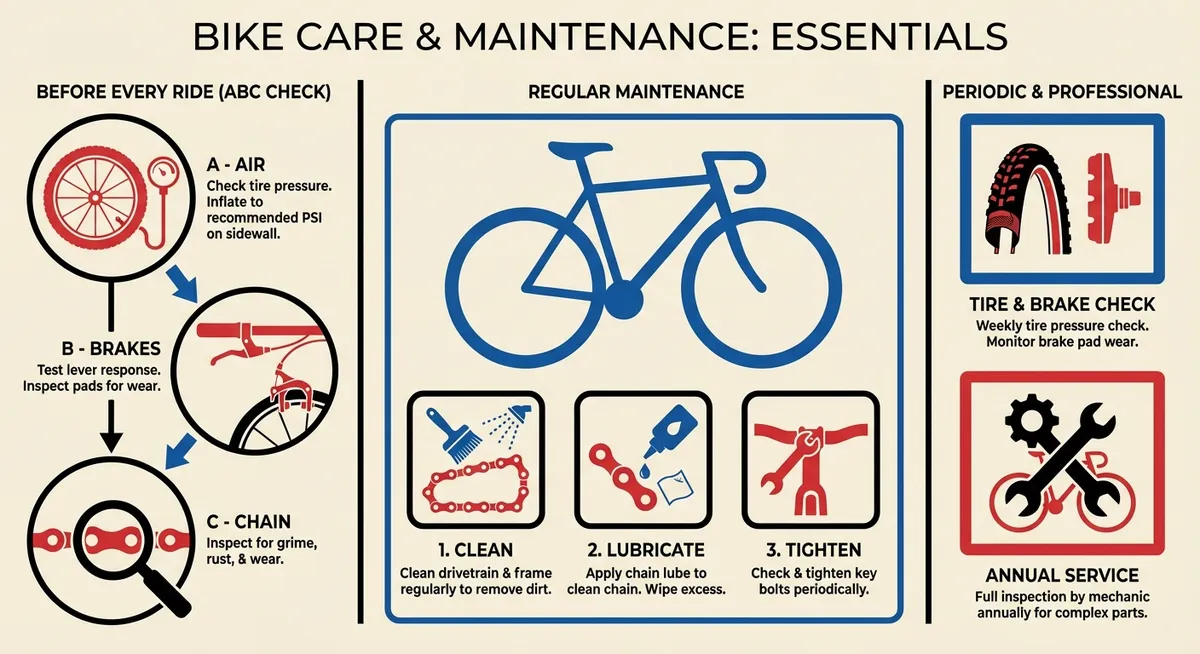
    Gemini 3 Pro Image connects a vast knowledge base to produce more factual assets over previous image generation models. Additionally, when enabled, grounding with Google Search connects the model to real-time web content for data-driven outputs. This is particularly valuable for applications requiring precise representations, such as biological diagrams or historical maps. Try this for yourself with our demo app where you can dynamically create infographics on any topic tailored to your audience.

    Bike care and maintenance infographic generated from a demo app that creates educational infographics.

    An infographic for bike care and maintenance essentials built with a simple text prompt using AI

    Go bananas and start building today

    This new model release incorporates much of the input you have already shared with us, but we aren’t stopping here. To ensure clear provenance in AI-generated media, we have integrated SynthID digital watermarks directly into every image created or edited with Gemini 3 Pro Image to denote its AI-generated or edited origin.

    Start by exploring our collection of apps that use Gemini 3 Pro Image to spark your imagination and see what’s possible. Once you’re inspired, remix these demo apps or integrate the model directly into your own projects via the Gemini API in Google AI Studio and Vertex AI for enterprise use. For technical details along the way, check out the documentation, prompt guide, cookbook or visit the developer forum to get help and share feedback.

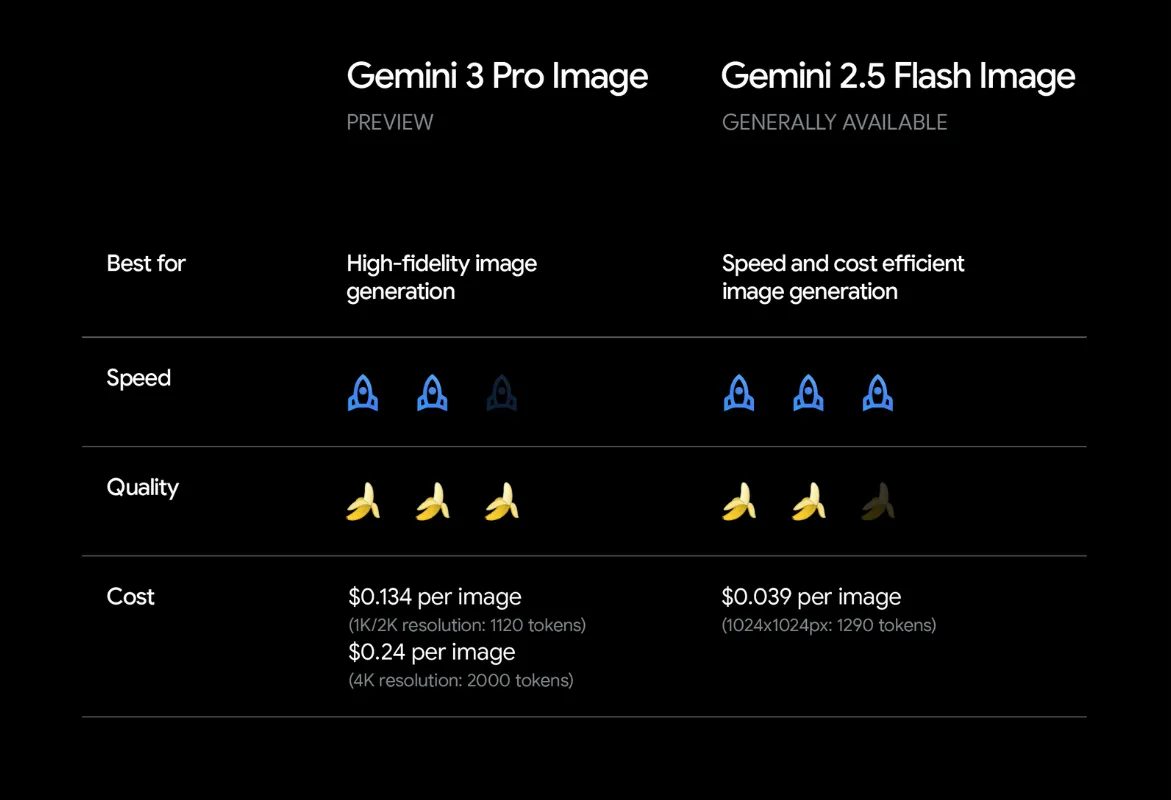
    Use Gemini 2.5 Flash Image for faster, lower cost image generation, or 3 Pro Image for higher quality image generation, with higher cost and latency.

    A table showing comparison between Gemini 2 Pro Image and Gemini 2.5 Flash Image models across speed, quality and cost

  • Introducing Nano Banana Pro

    Introducing Nano Banana Pro

    Turn your visions into studio-quality designs with unprecedented control, improved text rendering and enhanced world knowledge.


    Naina Raisinghani

    Product Manager, Google DeepMind


    Just a few months ago we released Nano Banana, our Gemini 2.5 Flash Image model. From restoring old photos to generating mini figurines, Nano Banana was a big step in image editing that empowered casual creators to express their creativity.
    Today, we’re introducing Nano Banana Pro (Gemini 3 Pro Image), our new state-of-the art image generation and editing model. Built on Gemini 3 Pro, Nano Banana Pro uses Gemini’s state-of-the-art reasoning and real-world knowledge to visualize information better than ever before.

    How Nano Banana Pro helps you bring any idea or design to life

    Nano Banana Pro can help you visualize any idea and design anything — from prototypes, to representing data as infographics, to turning handwritten notes into diagrams.

    With Nano Banana Pro, now you can:

    Generate more accurate, context-rich visuals based on enhanced reasoning, world knowledge and real-time information

    With Gemini 3’s advanced reasoning, Nano Banana Pro doesn’t just create beautiful images, it also helps you create more helpful content. You can get accurate educational explainers to learn more about a new subject, like context-rich infographics and diagrams based on the content you provide or facts from the real world. Nano Banana Pro can also connect to Google Search’s vast knowledge base to help you create a quick snapshot for a recipe or visualize real-time information like weather or sports.

    Infographic about plants using nano banana pro

    Infographic about making chai made using Nano Banana Pro

    Comic book style weather infographic using Nano Banana Pro

    Generate better visuals with more accurate, legible text directly in the image in multiple languages

    Nano Banana Pro is the best model for creating images with correctly rendered and legible text directly in the image, whether you’re looking for a short tagline, or a long paragraph. Gemini 3 is great at understanding depth and nuance, which unlocks a world of possibilities with image editing and generation — especially with text. Now you can create more detailed text in mockups or posters with a wider variety of textures, fonts and calligraphy. With Gemini’s enhanced multilingual reasoning, you can generate text in multiple languages, or localize and translate your content so you can scale internationally and/or share content more easily with friends and family.

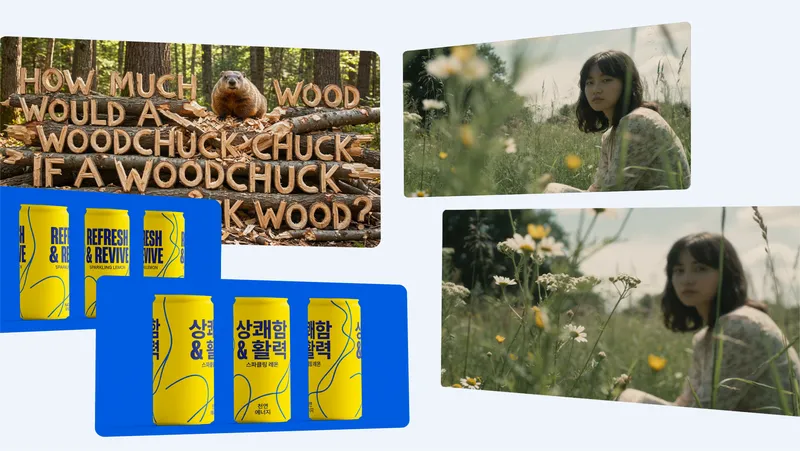
    Storyboard showing four panels for

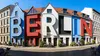
    Berlin street view with facades spelling

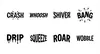
    Crash, whoosh, shiver, bang, drip, squeeze, roar, wobble in stylized fonts

    Cans in English and Korean

    The word

    Create high-fidelity visuals with upgraded creative capabilities

    • Consistency by design: With Nano Banana Pro, you can blend more elements than ever before, using up to 14 images and maintaining the consistency and resemblance of up to 5 people. Whether turning sketches into products or blueprints into photorealistic 3D structures, you can now bridge the gap between concept and creation. Apply your desired visual look and feel to your mockups with ease, ensuring your branding remains seamless and consistent across every touchpoint.

    Fluffy characters watching TV

    combining images of a gown, plants and a chair into one image

    generation of a futuristic sunset image

    Generated image of a fashion show from multiple elements

    • Studio-quality creative controls: With Nano Banana Pro’s new capabilities we are putting advanced creative controls directly into your hands. Select, refine and transform any part of an image with improved localized editing. Adjust camera angles, change the focus and apply sophisticated color grading, or even transform scene lighting (e.g. changing day to night or creating a bokeh effect). Your creations are ready for any platform, from social media to print, thanks to a range of available aspect ratios and available 2K and 4K resolution

    changing the aspect ratio of an image using Nano Banana

    A fox in the snow in the daytime and at night

    Changing the lighting on a man's face to just show the eyes

    Changing the focus on an image from a woman in a flower field to the flowers in the foreground

    How you can try Nano Banana Pro today

    Across our products and services, you now have a choice: the original Nano Banana for fast, fun editing, or Nano Banana Pro for complex compositions requiring the highest quality and visually sophisticated results.

    • Consumers and students: Rolling out globally in the Gemini app when you select ‘Create images’ with the ‘Thinking’ model. Our free-tier users will receive limited free quotas, after which they will revert to the original Nano Banana model. Google AI Plus, Pro and Ultra subscribers receive higher quotas. For AI Mode in Search, Nano Banana Pro is available in the U.S. for Google AI Pro and Ultra subscribers. For NotebookLM, Nano Banana Pro is also available for subscribers globally.
    • Professionals: We’re upgrading image generation in Google Ads to Nano Banana Pro to put cutting-edge creative and editing power directly into the hands of advertisers globally. It’s also rolling out starting today to Workspace customers in Google Slides and Vids.
    • Developers and enterprise: Starting to roll out in the Gemini API and Google AI Studio, and in Google Antigravity to create rich UX layouts & mockups; enterprises can start building in Vertex AI for scaled creation today and it’s coming soon to Gemini Enterprise.
    • Creatives: Starting to roll out to Google AI Ultra subscribers in Flow, our AI filmmaking tool, to give creatives, filmmakers and marketers even more precision and control over their frames and scenes.

    How to identify AI-generated images in the Gemini app

    We believe it’s critical to know when an image is AI-generated. This is why all media generated by Google’s tools are embedded with our imperceptible SynthID digital watermark.

    Today, we are putting a powerful verification tool directly in consumers’ hands: you can now upload an image into the Gemini app and simply ask if it was generated by Google AI, thanks to SynthID technology. We are starting with English language prompts for images, and will expand to more languages, audio and video soon.

    In addition to SynthID, we will maintain a visible watermark (the Gemini sparkle) on images generated by free and Google AI Pro tier users, to make images even more easy to detect as Google AI-generated.

    Recognizing the need for a clean visual canvas for professional work, we will remove the visible watermark from images generated by Google AI Ultra subscribers and within the Google AI Studio developer tool.

    You can find out more about how we’re increasing transparency in AI content with SynthID in our blog post.

    Related Article

    Build with Nano Banana Pro

    Nano Banana Pro, or Gemini 3 Pro Image, is our most advanced image generation and editing model.

    See more

    Image with multiple input-output images with the text Build with Nano Banana Pro in the center

    Related Article

    Nano Banana Pro prompting tips

    Here are some tips for writing more effective prompts for image generation and editing in Gemini using Nano Banana Pro.

    See more

    Collage of images created with Google AI Nano Banana Pro

  • Start building with Gemini 3

    Start building with Gemini 3

    Whether you’re an experienced developer or a vibe coder, Gemini 3 can help you bring any idea to life.


    Build anything with Gemini 3

    Today we are introducing Gemini 3, our most intelligent model that can help bring any idea to life. Built on a foundation of state-of-the-art reasoning, Gemini 3 Pro delivers unparalleled results across every major AI benchmark compared to previous versions. It also surpasses 2.5 Pro at coding, mastering both agentic workflows and complex zero-shot tasks.

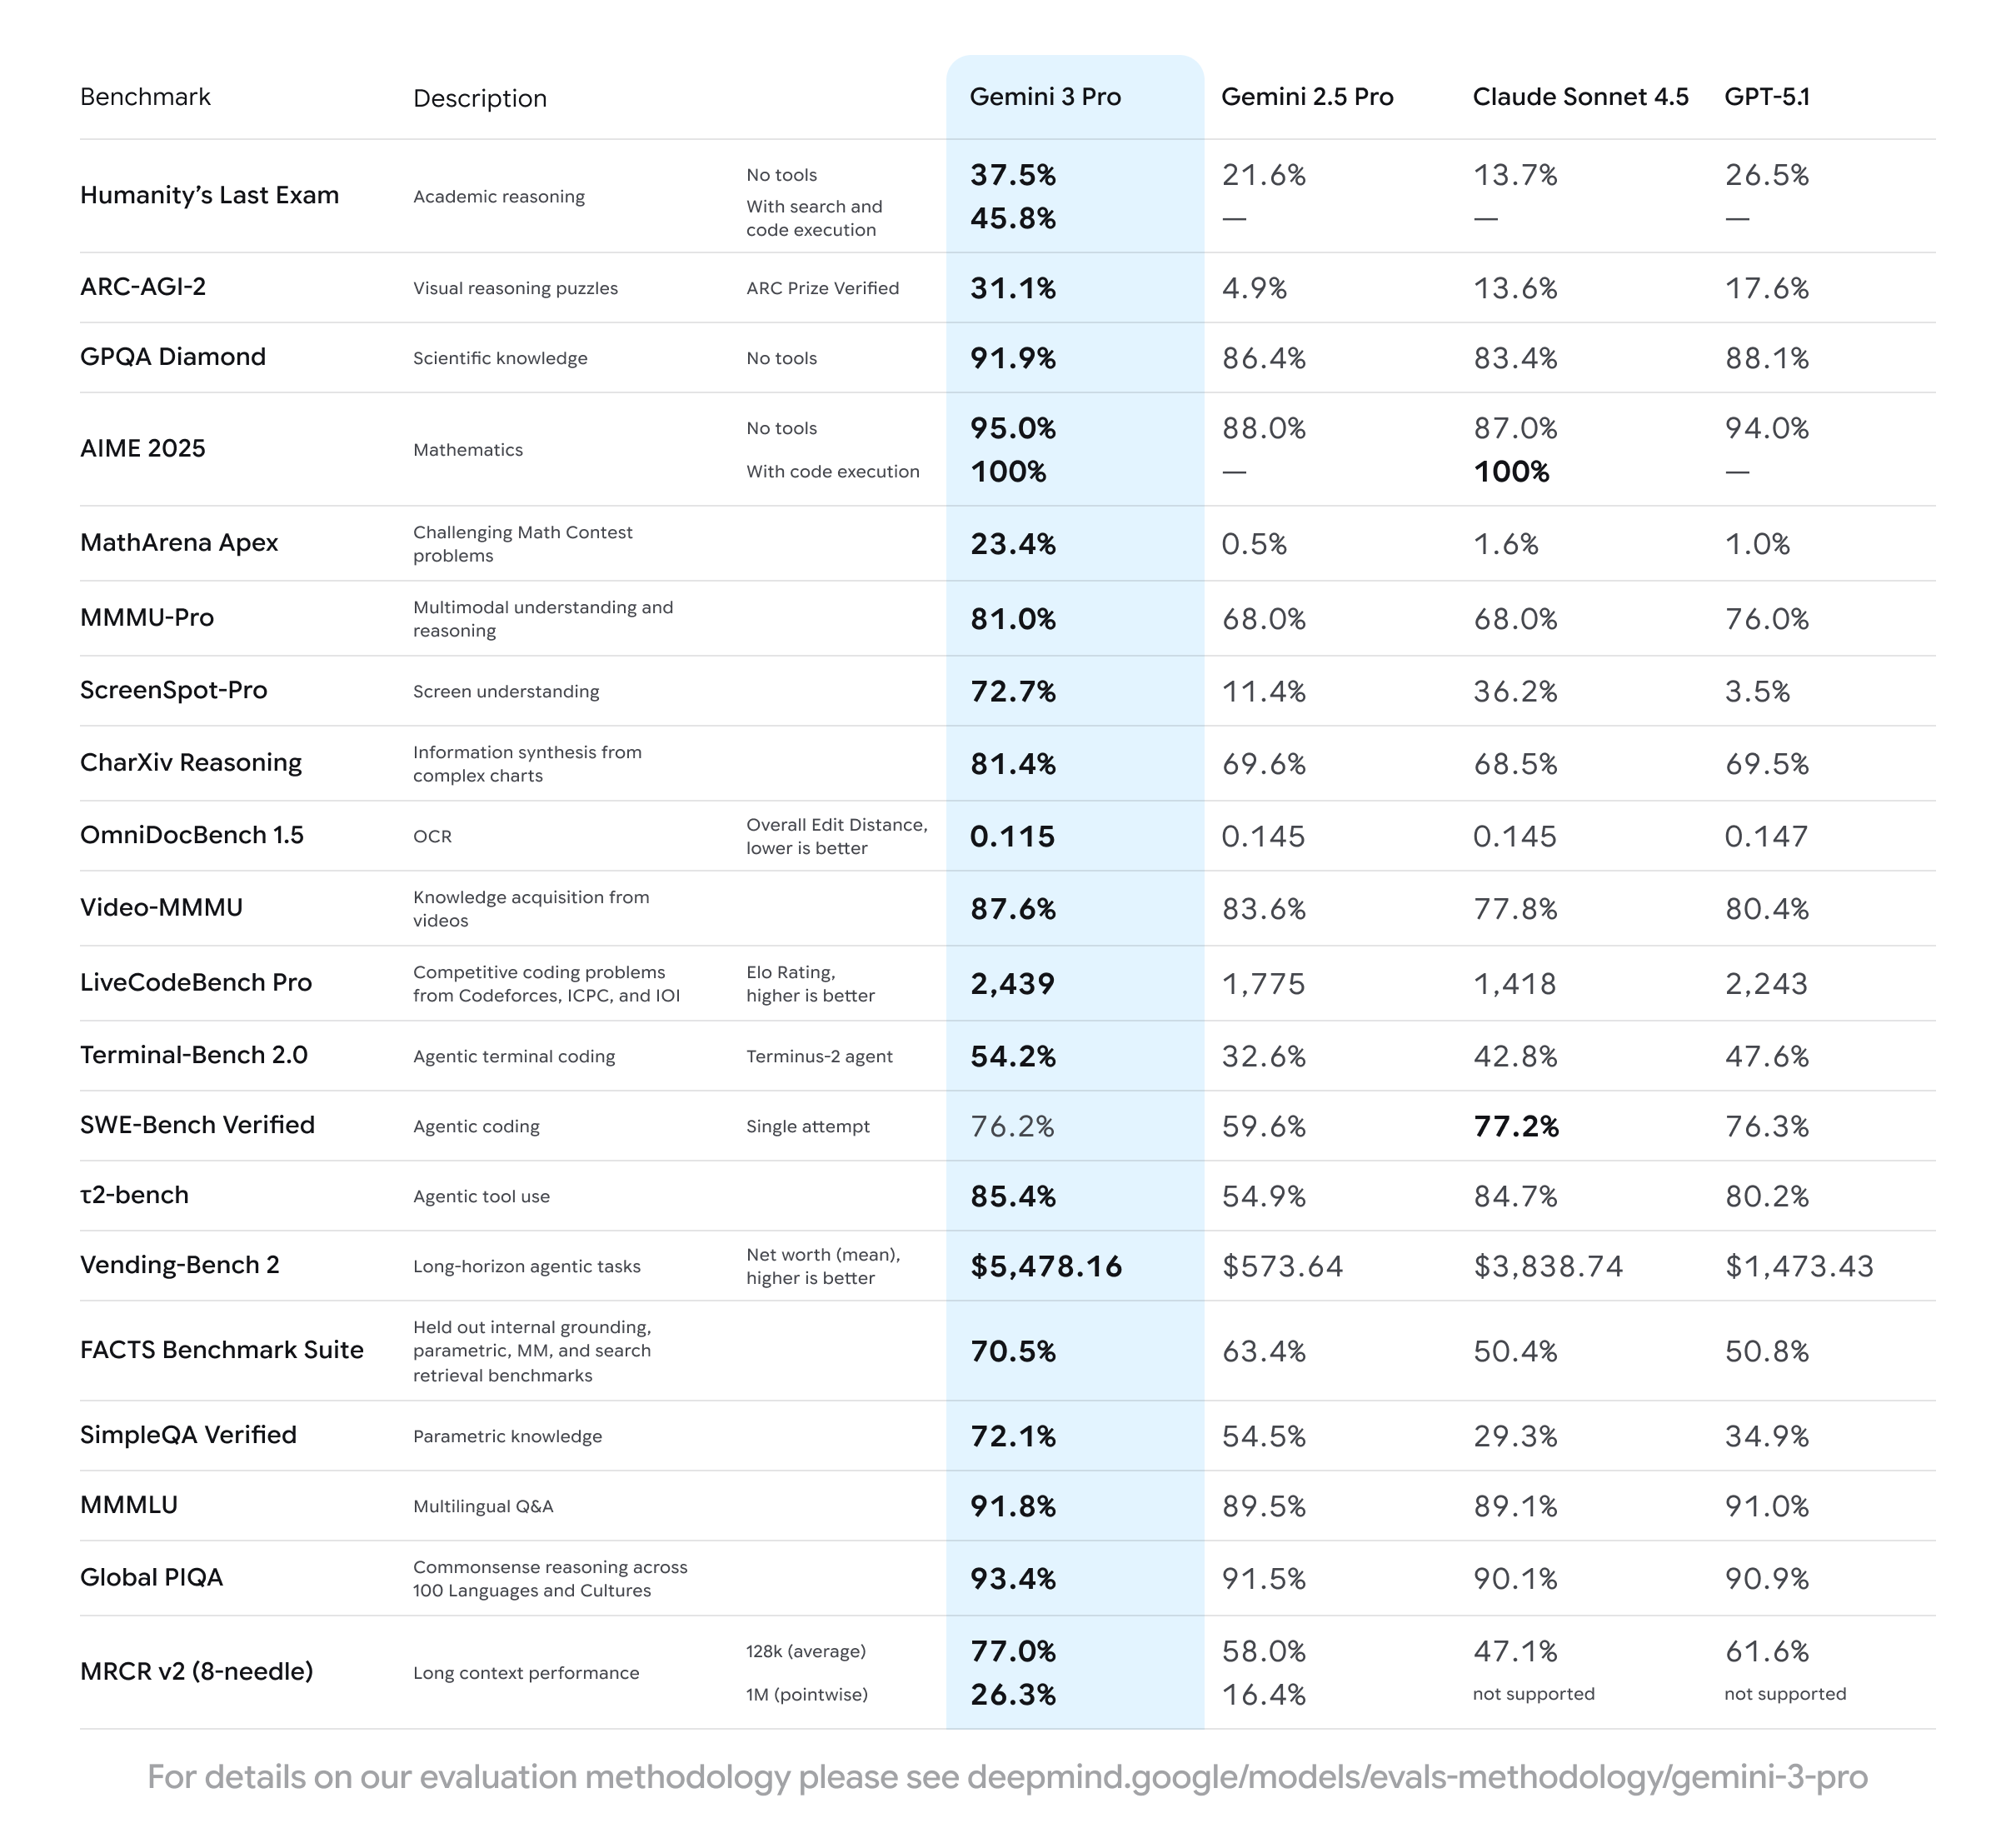
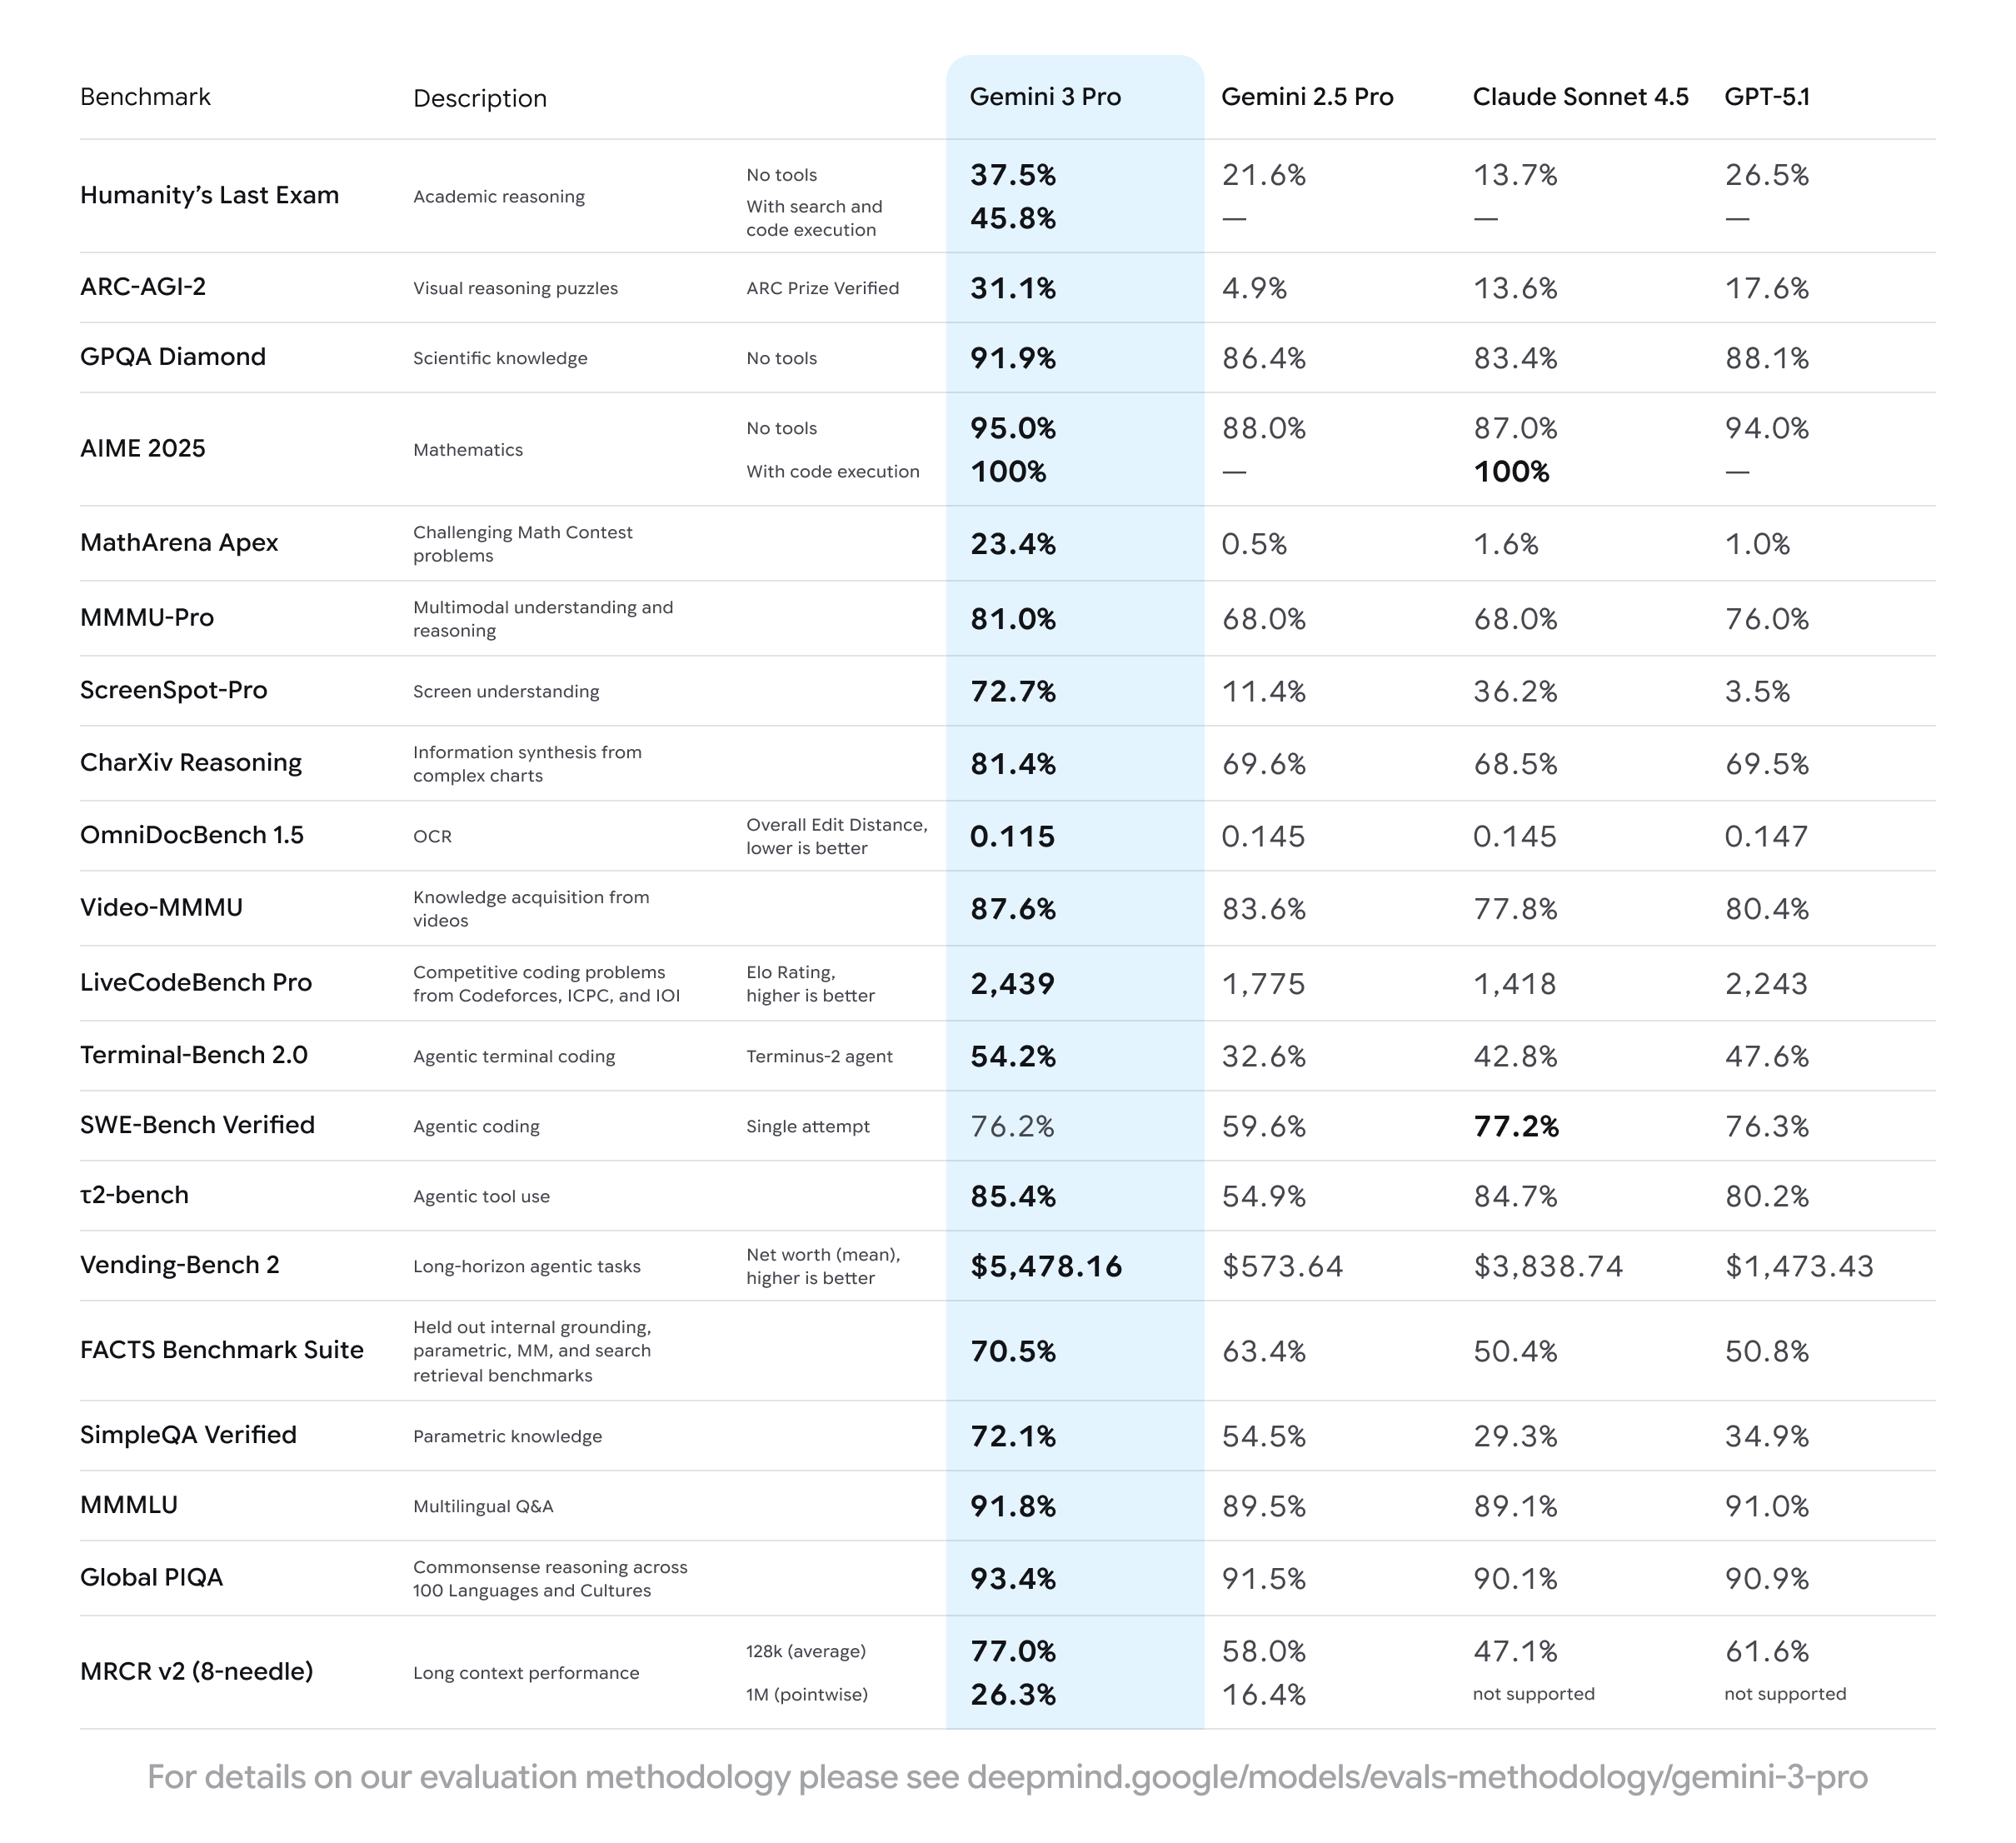
    Benchmarks table with comparison numbers for Gemini 3 Pro, Gemini 2.5 Pro, Claude Sonnet 4.5 and GPT-5.1

    Gemini 3 Pro fits right into existing production agent and coding workflows, while also enabling new use cases not previously possible. It’s available in preview at $2/million input tokens and $12/million output tokens for prompts 200k tokens or less through the Gemini API in Google AI Studio and Vertex AI for enterprises (see pricing for rate limits and full pricing details). Additionally, it can be utilized via your favorite developer tools within the broader ecosystem and is available, with rate limits, free of charge in Google AI Studio.

    Agentic coding

    Developers are spending more and more time creating software with AI at their side. Building on the momentum of Gemini 2.5 Pro and all the feedback, Gemini 3 Pro serves as a new foundation of intelligence for what’s possible with an agentic coding model.

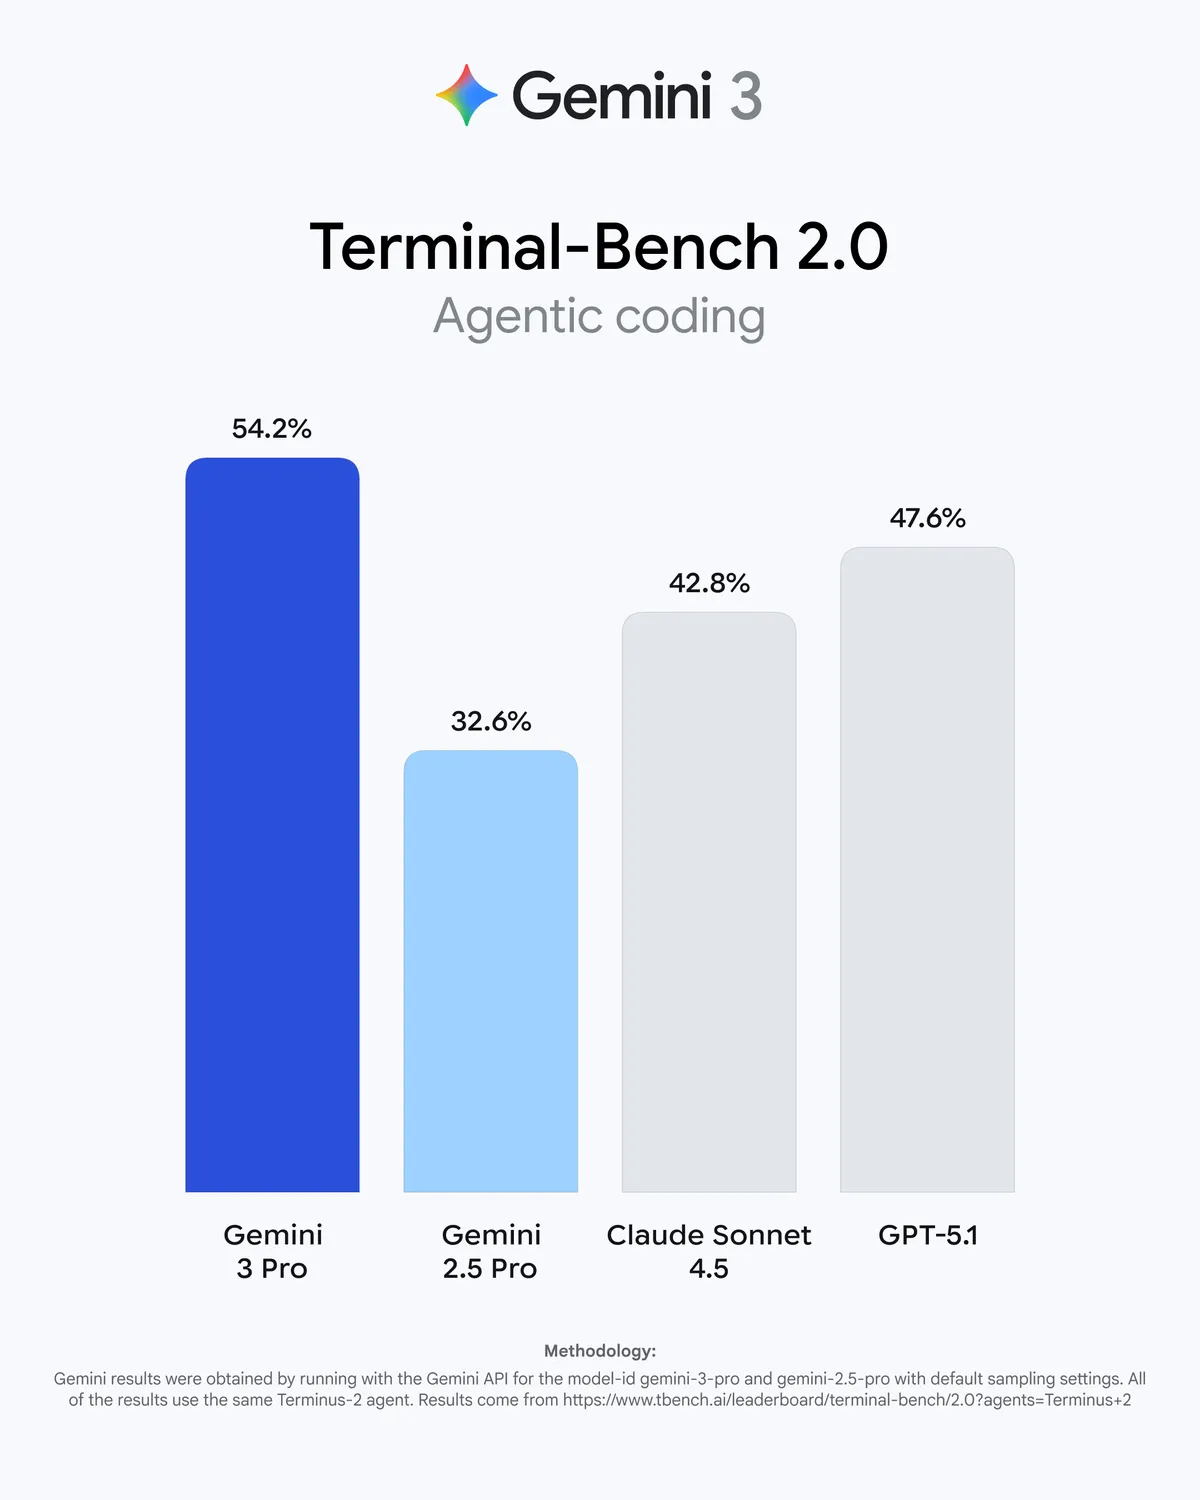
    Gemini 3 Pro scores 54.2% points on Terminal-Bench 2.0, which tests a model’s tool use ability to operate a computer via terminal.

    Terminal Bench evaluation charts for Gemini 3 and other AI models

    You can feel the power of this model come to life in Google Antigravity, our new agentic development platform, in addition to Gemini CLI, Android Studio, and other coding products like Cursor, GitHub, JetBrains, Manus, Cline and more.

    Google Antigravity

    To advance how the model and IDE work together, we’re introducing Google Antigravity to showcase what’s possible with Gemini 3. It’s an agentic development platform that enables developers to operate at a higher, task-oriented level by managing agents across workspaces, while retaining a familiar AI IDE experience at its core.

    It’s a faster way to develop: you act as the architect, collaborating with intelligent agents that operate autonomously across the editor, terminal, and browser. These agents plan and execute complex software tasks, communicating their work with the user via detailed artifacts. This elevates all aspects of development, from building features, UI iteration, and fixing bugs to researching and generating reports. Visit the Google Antigravity website to download the public preview at no charge, now available for MacOS, Windows and Linux.

    See multiple agents building in parallel in this multiplayer digital whiteboard app in Google Antigravity.
    ” video-id=”E-Sk9ypHVgI” video-type=”video”>

    Gemini API

    With Gemini 3, we are releasing a client-side bash tool that empowers the model to propose shell commands as part of agentic workflows for tasks such as navigating your local filesystem, driving development processes, and automating system operations. We’re pairing this with a hosted server-side bash tool for multi language code generation and secure prototyping. Available now in the Gemini API for early access partners, with general availability coming soon.

    Additionally, Gemini hosted tools Grounding with Google Search and URL context can now be combined with structured outputs. This is especially powerful for building agentic use cases which involve fetching and extracting data and then outputting them in a specific format for downstream agentic tasks.

    Vibe coding

    Gemini 3 Pro unlocks the true potential of “vibe coding”, where natural language is the only syntax you need. By significantly improving complex instruction following and deep tool use, the model can translate a high-level idea into a fully interactive app with a single prompt. It handles the heavy lifting of multi-step planning and coding details delivering richer visuals and deeper interactivity, allowing you to focus on the creative vision.

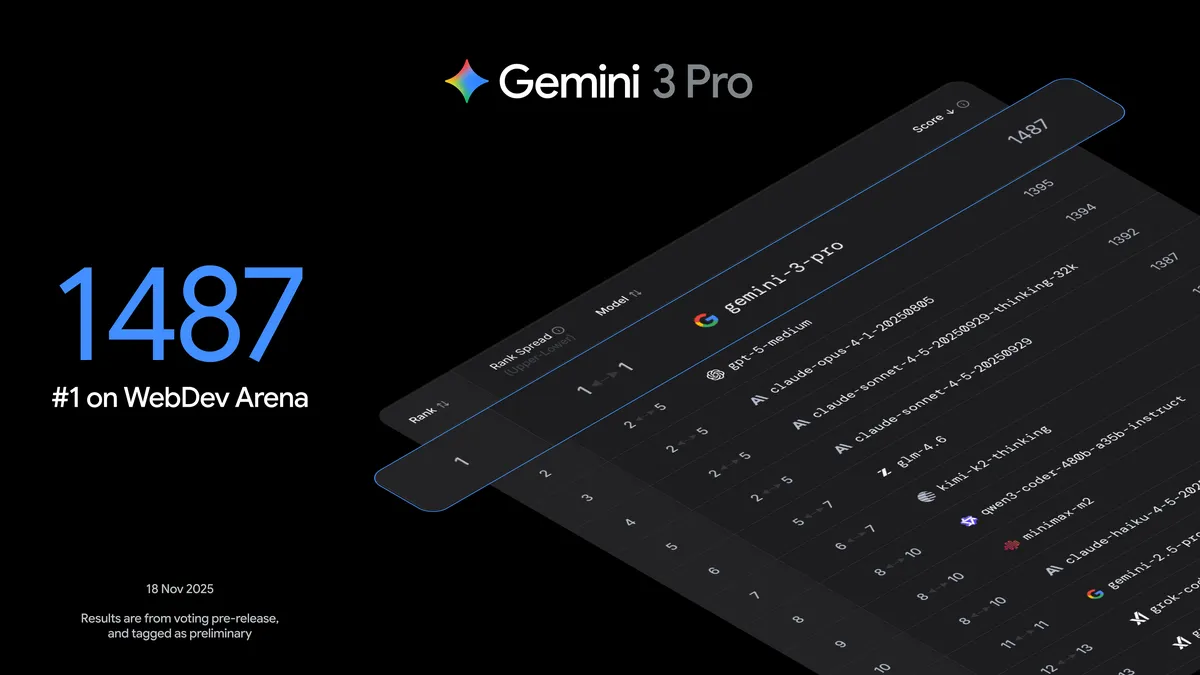
    Gemini 3 Pro tops the WebDev Arena leaderboard by scoring an impressive 1487 Elo.

    Graphic showing 1487 WebDev Arena leaderboard score

    Google AI Studio

    Whether it’s building a game with a single prompt, an interactive landing page from unstructured voice notes, or a full on app from a napkin sketch, developers can bring their idea to life with Gemini 3. With this model, we pushed single prompt generation capabilities further than ever, meaning you can go from idea to AI-powered app with a single prompt, like this retro game built in Google AI Studio.

    A zero-shot game built with Gemini 3 Pro in Google AI Studio.

    ” video-id=”Edol3PGrQQE” video-type=”video”>

    We’ve built Google AI Studio to be your fastest path from a prompt to an AI-native app. Build mode lets you add AI capabilities faster than ever, automatically wiring up the right models and APIs, while features like annotations enable fast and intuitive iteration. You can start building with Gemini 3 in Google AI Studio today.
    Multimodal understanding

    Gemini 3 is the best model in the world for complex multimodal understanding and sets new highs on MMMU-Pro for complex image reasoning and Video MMMU for video understanding. Combining its intelligence and a 1 million-token context window, developers can see significant improvements while building key multimodal use cases. To give you more control over latency and cost, you can now configure multimodal vision processing with more granularity in the Gemini API based on the visual fidelity required for your application.
    Visual reasoning

    Gemini 3 Pro is best-in-class for document understanding, going beyond simple OCR (Object Character Recognition) to intelligently handle complex document understanding and reasoning.

    You can see the model’s vision understanding, reasoning and coding capabilities in our demo app that brings any idea to life in Google AI Studio.

    With just an image, Gemini 3 Pro uses its vision understanding, reasoning and coding capabilities to turn it into an interactive web experience.

    ” video-id=”Avx2m5Igugo” video-type=”video”>

    Spatial reasoning

    The model’s improved spatial understanding also drives strong performance in embodied reasoning tasks like pointing, trajectory prediction and task progression, unlocking new use cases across autonomous vehicles, XR devices and robotics.

    Its spatial reasoning also powers intelligent screen understanding of desktop, mobile and OS screens delivering significant performance improvement for computer use agents. The model also understands the intent of user actions based on mouse movements and screen annotations unlocking novel experiences like this Visual Computer demo app.

    Gemini 3 not only comprehends the user’s hand-drawn instructions but also intelligently acts upon them based on its understanding of the screen and its elements.

” video-id=”nrfpu7mor6g” video-type=”video”>

Video reasoning

Gemini 3 Pro captures rapid action with high-frame-rate understanding, ensuring developers never miss a critical moment in fast-moving scenes. Beyond speed, long-context recall allows for synthesizing narratives and pinpointing specific details across hours of continuous footage.

Build what’s next, today

Gemini 3 Pro is now integrated into many developer products and tools to seamlessly fit into your existing workflows and unlock entirely new ways to code.

  • Build with the Gemini API: You can integrate Gemini 3 Pro immediately into your applications via Google AI Studio and Vertex AI for Enterprise. To support the model’s deeper reasoning capabilities, we’re introducing a new thinking level and more granular media resolution parameters in the API, along with stricter validation for thought signatures. This update is critical for preserving the model’s thoughts across multi-turn conversations. Check out the Developer Guide for the technical breakdown and our Prompting Guide to learn how to build with Gemini 3 Pro.
  • Experience the model’s agentic capabilities: Whether you are adding AI-native features to an Android app, automating workflows through Gemini CLI or managing a fleet of autonomous agents in Google Antigravity, Gemini 3 Pro provides the reliability needed for complex, agentic architectures.
  • Vibe code with Gemini 3 Pro: Google AI Studio is your fastest path to bring any idea to life. Get started in Build mode to generate a fully functional app with a single prompt. And if you need a little inspiration, click “I’m feeling lucky” and let Gemini 3 Pro handle the creative spark and the code implementation simultaneously.

The software landscape is shifting. As AI changes who builds and how they build, we are committed to meeting you where you are — giving you the tools to push the boundaries of what’s possible.

This is just the start of the Gemini 3 era but we can’t wait to see what you build with Gemini 3 Pro!

  • We’re expanding our presence in Singapore to advance AI in the Asia-Pacific region

    We’re expanding our presence in Singapore to advance AI in the Asia-Pacific region

    November 19, 2025 Responsibility & Safety

    Lila Ibrahim, Chief Operating Officer, Google DeepMind

    Through cutting-edge research, a growing bench of world-class talent, and deepening work with government, we’ll accelerate real-world benefits and applications of AI

    The Asia-Pacific region is home to more than half the world’s population and is poised for immense growth. The Singapore government’s ambitious and forward-looking approach — exemplified by their National AI Strategy 2.0 and Smart Nation 2.0 and their openness to global talent — make this an excellent location to expand our presence as we open a new Google DeepMind research lab in Singapore.

    This investment builds on Google’s longstanding commitment to the Asia-Pacific ecosystem, and follows a more-than doubling of Google DeepMind’s APAC team over the past year.

    Advancing Gemini and frontier AI impact

    Our growing team in Singapore will consist of exceptional research scientists, software engineers, and AI impact experts focused on critical areas of research and development. This builds on our efforts to pioneer foundational research in linguistic and cultural inclusivity for Asia Pacific, advance Gemini’s core capabilities, and apply the latest models across Google products and for Cloud customers.

    Our new research lab will be focused on collaboration as we work directly with government, businesses, civil society and world-class academic institutions across the region. We are focused on understanding how our technologies can be best built to serve the diverse needs of the Asia-Pacific region.

    Building on a foundation of positive impact

    We are already seeing the extraordinary positive impact that our teams and partners are generating by applying Google technologies across Singapore and the wider region. Beyond our core products like Gemini, we are seeing creative and exciting examples of our AI technology in action when used collaboratively and responsibly:

    • In Science: A multidisciplinary research team at Singapore’s Agency of Science, Technology and Research (A*STAR) and the National Neuroscience Institute (NNI) used AlphaFold to pioneer a breakthrough in understanding Parkinson’s disease, establishing a link between immunology and neurodegenerative diseases that could lead to earlier diagnosis and targeted therapies.
    • In Public Services: We are working closely with GovTech, the Cyber Security Agency of Singapore (CSA), and the Infocomm Media Development Authority (IMDA). Together, we launched an AI agent sandbox to safely test autonomous solutions that enhance public sector efficiency and service delivery.
    • Regarding multilinguality: We have collaborated with AI Singapore to launch Project Aquarium, an open data platform for Southeast Asian Languages. We’ve also expanded our partnership to support further developments of SEA-LION – a family of LLMs trained and tuned to be representative of Southeast Asia’s cultural contexts and linguistic nuances. This enabled the launch of their first multimodal model, SEA-LION v4, built on Gemma 3’s multimodal capabilities.
    • In Education: We are giving students in Singapore one-year free access to the Google AI Pro Plan to unlock upgraded AI features for creativity and learning, and we introduced Gemini Academy to IMDA’s Singapore Digital Office to broaden AI literacy and make AI accessible to all.
    • With Startups: Through our Google for Startups: AI First accelerator, we are supporting Singaporean AI-first startups that are using generative AI to tackle significant economic, societal and environmental issues.

    These examples reflect what’s possible when cutting-edge AI research meets Singapore’s forward-looking innovation and strong public purpose.

    Our shared vision for the future

    As we expand our presence in Singapore, we’re committed to ensuring the benefits of AI are realized across the region. Through our new AI research lab, we will continue collaborating with the region’s vibrant ecosystem of partners to unlock AI’s transformative benefits for diverse communities. Together, we are responsibly shaping how AI can serve the needs, and reflect the cultures, of over half the world’s population.

  • A new era of intelligence with Gemini 3

    A new era of intelligence with Gemini 3

    Gemini 3 is our most intelligent model that helps you bring any idea to life.


    Gemini 3 logo in front of a black background with the number 3 in blue dots

    Your browser does not support the audio element.

    Listen to article

    [[duration]] minutes

    This content is generated by Google AI. Generative AI is experimental

    A note from Google and Alphabet CEO Sundar Pichai:

    Nearly two years ago we kicked off the Gemini era, one of our biggest scientific and product endeavors ever undertaken as a company. Since then, it’s been incredible to see how much people love it. AI Overviews now have 2 billion users every month. The Gemini app surpasses 650 million users per month, more than 70% of our Cloud customers use our AI, 13 million developers have built with our generative models, and that is just a snippet of the impact we’re seeing.

    And we’re able to get advanced capabilities to the world faster than ever, thanks to our differentiated full stack approach to AI innovation — from our leading infrastructure to our world-class research and models and tooling, to products that reach billions of people around the world.

    Every generation of Gemini has built on the last, enabling you to do more. Gemini 1’s breakthroughs in native multimodality and long context window expanded the kinds of information that could be processed — and how much of it. Gemini 2 laid the foundation for agentic capabilities and pushed the frontiers on reasoning and thinking, helping with more complex tasks and ideas, leading to Gemini 2.5 Pro topping LMArena for over six months.

    And now we’re introducing Gemini 3, our most intelligent model, that combines all of Gemini’s capabilities together so you can bring any idea to life.

    It’s state-of-the-art in reasoning, built to grasp depth and nuance — whether it’s perceiving the subtle clues in a creative idea, or peeling apart the overlapping layers of a difficult problem. Gemini 3 is also much better at figuring out the context and intent behind your request, so you get what you need with less prompting. It’s amazing to think that in just two years, AI has evolved from simply reading text and images to reading the room.

    And starting today, we’re shipping Gemini at the scale of Google. That includes Gemini 3 in AI Mode in Search with more complex reasoning and new dynamic experiences. This is the first time we are shipping Gemini in Search on day one. Gemini 3 is also coming today to the Gemini app, to developers in AI Studio and Vertex AI, and in our new agentic development platform, Google Antigravity — more below.

    Like the generations before it, Gemini 3 is once again advancing the state of the art. In this new chapter, we’ll continue to push the frontiers of intelligence, agents, and personalization to make AI truly helpful for everyone.

    We hope you like Gemini 3, we’ll keep improving it, and look forward to seeing what you build with it. Much more to come!


    Introducing Gemini 3: our most intelligent model that helps you bring any idea to life

    Demis Hassabis, CEO of Google DeepMind and Koray Kavukcuoglu, CTO of Google DeepMind and Chief AI Architect, Google, on behalf of the Gemini team

    Today we’re taking another big step on the path toward AGI and releasing Gemini 3.

    It’s the best model in the world for multimodal understanding and our most powerful agentic and vibe coding model yet, delivering richer visualizations and deeper interactivity — all built on a foundation of state-of-the-art reasoning.

    We’re beginning the Gemini 3 era by releasing Gemini 3 Pro in preview and making it available today across a suite of Google products so you can use it in your daily life to learn, build and plan anything. We’re also introducing Gemini 3 Deep Think — our enhanced reasoning mode that pushes Gemini 3 performance even further — and giving access to safety testers before making it available to Google AI Ultra subscribers.

    State-of-the-art reasoning with unprecedented depth and nuance

    Gemini 3 Pro can bring any idea to life with its state-of-the-art reasoning and multimodal capabilities. It significantly outperforms 2.5 Pro on every major AI benchmark.

    It tops the LMArena Leaderboard with a breakthrough score of 1501 Elo. It demonstrates PhD-level reasoning with top scores on Humanity’s Last Exam (37.5% without the usage of any tools) and GPQA Diamond (91.9%). It also sets a new standard for frontier models in mathematics, achieving a new state-of-the-art of 23.4% on MathArena Apex.

    Beyond text, Gemini 3 Pro redefines multimodal reasoning with 81% on MMMU-Pro and 87.6% on Video-MMMU. It also scores a state-of-the-art 72.1% on SimpleQA Verified, showing great progress on factual accuracy. This means Gemini 3 Pro is highly capable at solving complex problems across a vast array of topics like science and mathematics with a high degree of reliability.

    Gemini 3 evaluation table against other AI models

    Gemini 3 Pro also brings a new level of depth and nuance to every interaction. Its responses are smart, concise and direct, trading cliché and flattery for genuine insight — telling you what you need to hear, not just what you want to hear. It acts as a true thought partner that gives you new ways to understand information and express yourself, from translating dense scientific concepts by generating code for high-fidelity visualizations to creative brainstorming.

    Gemini 3 can code a visualization of plasma flow in a tokamak and write a poem capturing the physics of fusion.

    Gemini 3 Deep Think

    Gemini 3 Deep Think mode pushes the boundaries of intelligence even further, delivering a step-change in Gemini 3’s reasoning and multimodal understanding capabilities to help you solve even more complex problems.

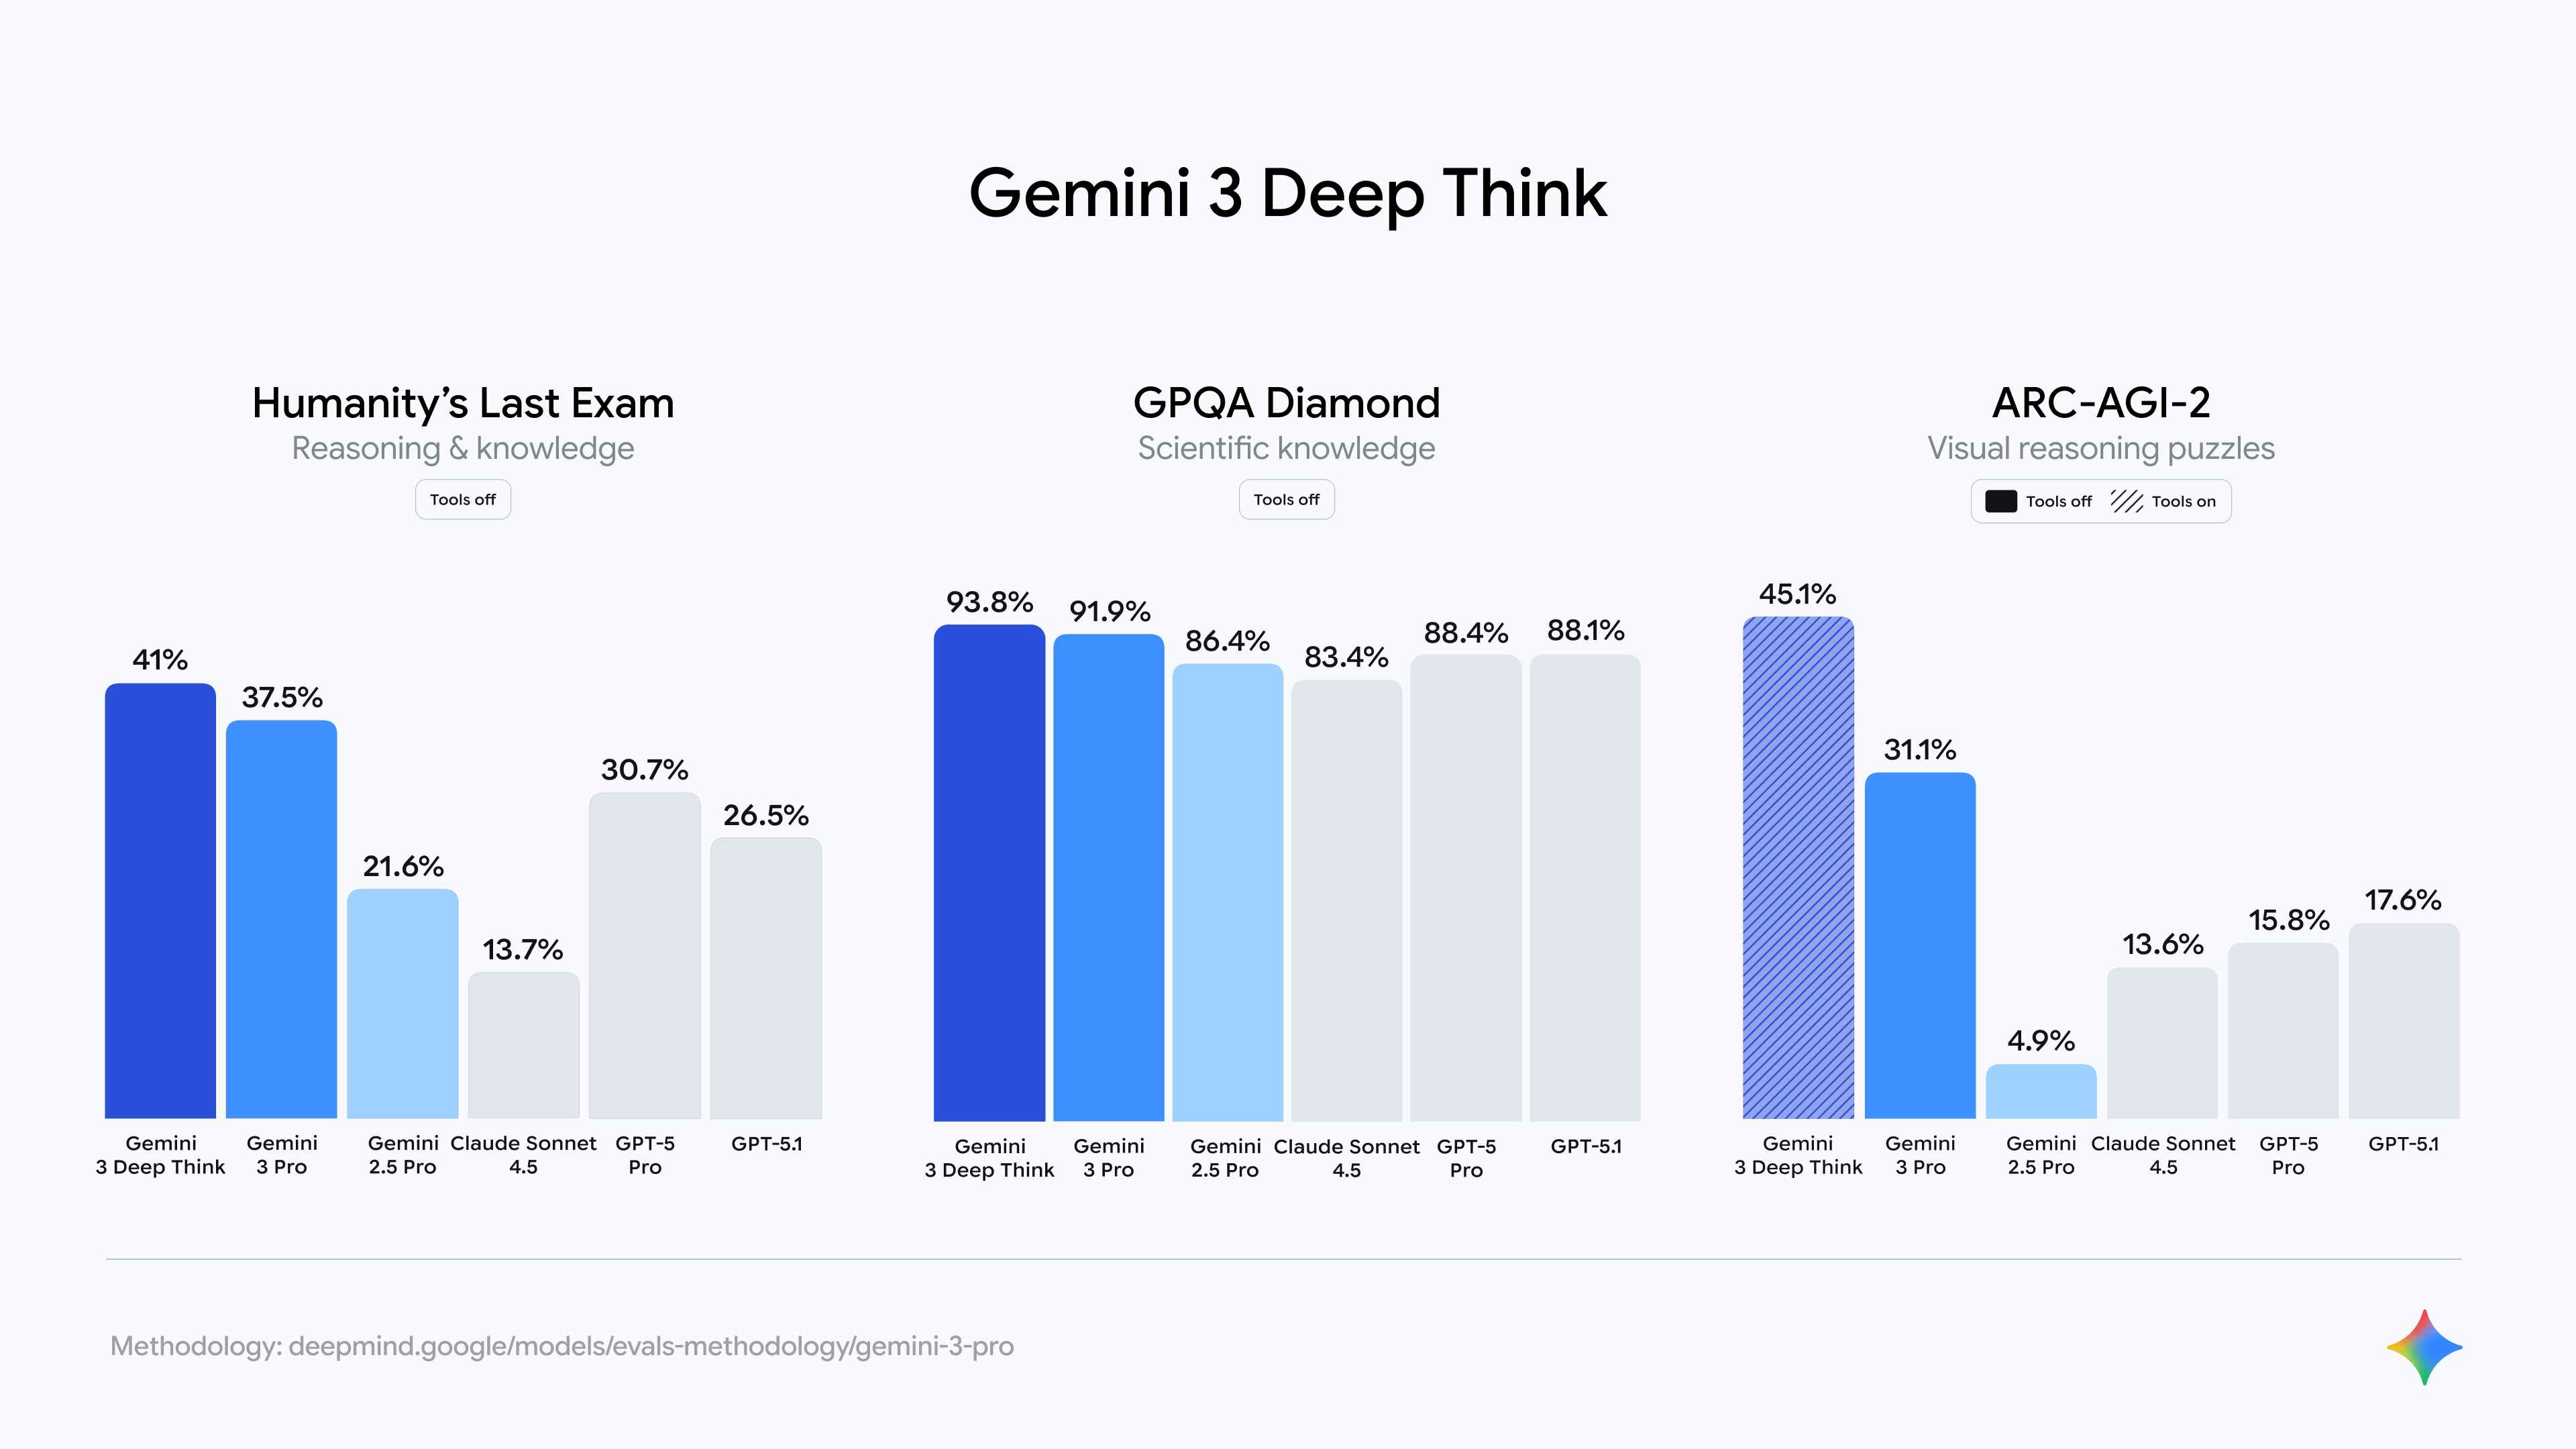
    In testing, Gemini 3 Deep Think outperforms Gemini 3 Pro’s already impressive performance on Humanity’s Last Exam (41.0% without the use of tools) and GPQA Diamond (93.8%). It also achieves an unprecedented 45.1% on ARC-AGI-2 (with code execution, ARC Prize Verified), demonstrating its ability to solve novel challenges.

    Gemini 3 Deep Think mode excels on some of the most challenging AI benchmarks. See details on our evaluation methodology.

    Evaluation chart for Gemini 3 Deep Think

    Gemini 3 helps you learn, build and plan anything

    Learn anything

    Gemini was built from the start to seamlessly synthesize information about any topic across multiple modalities, including text, images, video, audio and code. Gemini 3 pushes the frontier of multimodal reasoning to help you learn in ways that make sense for you by combining its state-of-the-art reasoning, vision and spatial understanding, leading multilingual performance, and 1 million-token context window.

    For example, if you want to learn how to cook in your family tradition, Gemini 3 can decipher and translate handwritten recipes in different languages into a shareable family cookbook. Or if you want to learn about a new topic, you can give it academic papers, long video lectures or tutorials and it can generate code for interactive flashcards, visualizations or other formats that will help you master the material. It can even analyze videos of your pickleball match, identify areas where you can improve and generate a training plan for overall form improvements.

    To help you make better sense of information on the web, AI Mode in Search now uses Gemini 3 to enable new generative UI experiences like immersive visual layouts and interactive tools and simulations, all generated completely on the fly based on your query.

    Build anything

    Building on the success of 2.5 Pro, Gemini 3 delivers on the promise of bringing any idea to life for developers. It’s exceptional at zero-shot generation and handles complex prompts and instructions to render richer, more interactive web UI.

    Gemini 3 is the best vibe coding and agentic coding model we’ve ever built – making our products more autonomous and boosting developer productivity. It tops the WebDev Arena leaderboard by scoring an impressive 1487 Elo. It also scores 54.2% on Terminal-Bench 2.0, which tests a model’s tool use ability to operate a computer via terminal and it greatly outperforms 2.5 Pro on SWE-bench Verified (76.2%), a benchmark that measures coding agents.

    You can now build with Gemini 3 in Google AI Studio, Vertex AI, Gemini CLI and our new agentic development platform, Google Antigravity. It’s also available in third-party platforms like Cursor, GitHub, JetBrains, Manus, Replit and more.

    Introducing a new agent-first development experience

    As model intelligence accelerates with Gemini 3, we have the opportunity to reimagine the entire developer experience. Today we’re releasing Google Antigravity, our new agentic development platform that enables developers to operate at a higher, task-oriented level.

    Using Gemini 3’s advanced reasoning, tool use and agentic coding capabilities, Google Antigravity transforms AI assistance from a tool in a developer’s toolkit into an active partner. While the core of Google Antigravity is a familiar AI IDE experience, its agents have been elevated to a dedicated surface and given direct access to the editor, terminal and browser. Now, agents can autonomously plan and execute complex, end-to-end software tasks simultaneously on your behalf while validating their own code.

    In addition to Gemini 3 Pro, Google Antigravity also comes tightly coupled with our latest Gemini 2.5 Computer Use model for browser control and our top-rated image editing model Nano Banana (Gemini 2.5 Image).

    Google Antigravity uses Gemini 3 to drive an end-to-end agentic workflow for a flight tracker app. The agent independently plans, codes the application and validates its execution through browser-based computer use.

    Plan anything

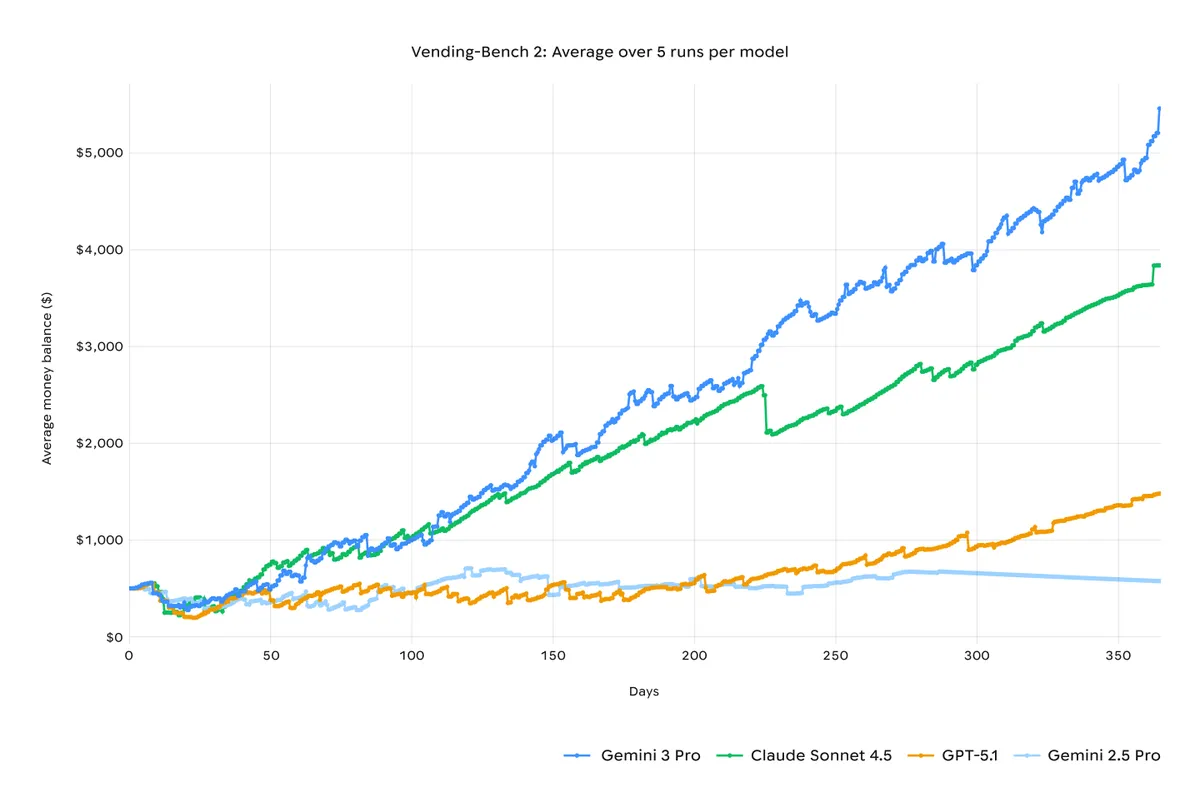
    Since introducing the agentic era with Gemini 2, we’ve made a lot of progress, not only advancing Gemini’s coding agent abilities, but also improving its ability to reliably plan ahead over longer horizons. Gemini 3 demonstrates this by topping the leaderboard on Vending-Bench 2, which tests longer horizon planning by managing a simulated vending machine business. Gemini 3 Pro maintains consistent tool usage and decision-making for a full simulated year of operation, driving higher returns without drifting off task.

    Gemini 3 Pro demonstrates better long-horizon planning to generate significantly higher returns compared to other frontier models.

    Chart showing Gemini 3 Pro outperforming other AI models on long-horizon planning

    This means Gemini 3 can better help you get things done in everyday life. By combining deeper reasoning with improved, more consistent tool use, Gemini 3 can take action on your behalf by navigating more complex, multi-step workflows from start to finish — like booking local services or organizing your inbox — all while under your control and guidance.

    Google AI Ultra subscribers can try these agentic capabilities in the Gemini app with Gemini Agent today. We’ve learned a lot improving Gemini’s agentic capabilities, and we’re excited to see how you use it as we expand to more Google products soon.

    Building Gemini 3 responsibly

    Gemini 3 is our most secure model yet, and has undergone the most comprehensive set of safety evaluations of any Google AI model to date. The model shows reduced sycophancy, increased resistance to prompt injections and improved protection against misuse via cyberattacks.

    In addition to our in-house testing for the critical domains in our Frontier Safety Framework, we’ve also partnered on evaluations with world-leading subject matter experts, provided early access to bodies like the UK AISI, and obtained independent assessments from industry experts like Apollo, Vaultis, Dreadnode and more. For more information, see the Gemini 3 model card.

    The next era of Gemini

    This is just the start of the Gemini 3 era. As of today, Gemini 3 starts rolling out:

    • For everyone in the Gemini app and for Google AI Pro and Ultra subscribers in AI Mode in Search
    • For developers in the Gemini API in AI Studio, our new agentic development platform, Google Antigravity; and Gemini CLI
    • For enterprises in Vertex AI and Gemini Enterprise

    For Gemini 3 Deep Think mode, we’re taking extra time for safety evaluations and input from safety testers before making it available to Google AI Ultra subscribers in the coming weeks.

    We plan to release additional models to the Gemini 3 series soon so you can do more with AI. We look forward to getting your feedback and seeing what you learn, build and plan with Gemini.

    Collection

    Introducing Gemini 3

    Gemini 3, our most intelligent model, combines all of Gemini’s capabilities together so you can bring any idea to life.

    See more

    Gemini 3 logo

  • Introducing Google Antigravity

    Introducing Google Antigravity

    Every advancement in model intelligence for coding has encouraged us to rethink how development should be done. The Integrated Development Environment (IDE) of today is a far cry from the IDE of just a few years ago. Gemini 3, our most intelligent model, represents a step-change for agentic coding, and requires us to think about what the next step-change of an IDE should be.

    Today, we are introducing Google Antigravity, our new agentic development platform. While the core is a familiar AI-powered IDE experience with the best of Google’s models, Antigravity is evolving the IDE towards an agent-first future with browser control capabilities, asynchronous interaction patterns, and an agent-first product form factor that together, enable agents to autonomously plan and execute complex, end-to-end software tasks.

    Why we built Antigravity

    We want Antigravity to be the home base for software development in the era of agents. Our vision is to ultimately enable anyone with an idea to experience liftoff and build that idea into reality. From today, Google Antigravity is available in public preview at no charge, with generous rate limits on Gemini 3 Pro usage.

    With models like Gemini 3, we have started hitting the point in agentic intelligence where models are capable of running for longer periods of time without intervention across multiple surfaces. Not yet for days at a time without intervention, but we’re getting closer to a world where we interface with agents at higher abstractions over individual prompts and tool calls. In this world, the product surface that enables communication between the agent and user should look and feel different — and Antigravity is our answer to this.

    Core tenets

    Antigravity is our first product that brings four key tenets of collaborative development together: trust, autonomy, feedback, and self-improvement.

    Trust

    Most products today live in one of two extremes: either they show the user every single action and tool call the agent has made or they only show the final code change with no context on how the agent got there, and with no easy way to verify the work. Neither engenders user trust in the work that the agent undertook. Antigravity provides context on agentic work at a more natural task-level abstraction, with the necessary and sufficient set of artifacts and verification results, for the user to gain that trust. There is a concerted emphasis for the agent to thoroughly think through verification of its work, not just the work itself.

    In a conversation with an agent in Antigravity, the user sees tool calls grouped within tasks, monitoring high-level summaries and progress along that task. As the agent works, it produces Artifacts, tangible deliverables in formats that are easier for users to validate than raw tool calls, such as task lists, implementation plans, walkthroughs, screenshots, and browser recordings. Agents in Antigravity use Artifacts to communicate to the user that it understands what it is doing and that it is thoroughly verifying its work.

    View the Agent's task list,review the implementation plan post-research and pre-implementation,or scan the walkthrough at completion.

    View the Agent’s task list,review the implementation plan post-research and pre-implementation,or scan the walkthrough at completion.

    Autonomy

    Today, the most intuitive product form factor is working synchronously with an agent embedded within a surface (such as an editor, browser, or terminal). That is why Antigravity’s primary “Editor view” is a state-of-the-art AI-powered IDE experience, with Tab completions, in-line Commands, and a fully functioning agent in the side panel.

    That being said, we are transitioning to an era, with models like Gemini 3, when agents can operate across all of these surfaces simultaneously and autonomously:

    Autonomously,an Antigravity Agent writes code for a new frontend feature,uses the terminal to launch localhost,and actuates the browser to test that the new feature works.

    Autonomously,an Antigravity Agent writes code for a new frontend feature,uses the terminal to launch localhost,and actuates the browser to test that the new feature works.

    We also believe agents deserve a form factor that exposes this autonomy optimally and allows users to interact with them more asynchronously. So, in addition to the IDE-like Editor surface, we are introducing an agent-first Manager surface, which flips the paradigm of agents being embedded within surfaces to one where the surfaces are embedded into the agent. You can think of it like a mission control for spawning, orchestrating, and observing multiple agents across multiple workspaces in parallel.

    User spawned an Agent to do background research in a different workspace while focusing on a more involved task in the foreground,using the Inbox and side panel in the Agent Manager to be notified of progress.

    User spawned an Agent to do background research in a different workspace while focusing on a more involved task in the foreground,using the Inbox and side panel in the Agent Manager to be notified of progress.

    We decided not to try to squeeze both the asynchronous Manager experience and the synchronous Editor experience into a single window, rather optimizing for instantaneous handoffs between the Manager and Editor. Antigravity is designed to be forward-looking, intuitively bringing development to the asynchronous era as models like Gemini continue to rapidly get smarter.

    Feedback

    A core failing of a remote-only form factor is the inability to iterate easily with the agent. Agentic intelligence has indeed improved significantly, but it is still not perfect. An agent being able to complete 80% of the work should be useful, but if there is no easy way to provide feedback, then it becomes more work than benefit to resolve the remaining 20%. User feedback allows us to not treat an agent as a black-or-white system that either is perfect or unhelpful. Antigravity is starting with local operation, allowing intuitive async user feedback across every surface and Artifact, whether it be Google-doc-style comments on text Artifacts or select-and-comment feedback on screenshots. This feedback is automatically incorporated into the agent’s execution without requiring you to stop the agent’s process.

    An example of feedback on textual Artifacts such as an implementation plan and an example of feedback on a visual Artifact such as a screenshot taken by the Agent.

    An example of feedback on textual Artifacts such as an implementation plan and an example of feedback on a visual Artifact such as a screenshot taken by the Agent.

    Self-improvement

    Antigravity treats learning as a core primitive, with agent actions both retrieving from and contributing to a knowledge base. This knowledge management allows the agent to learn from past work. This could be important explicit information such as useful snippets of code or derived architecture, but could also be more abstract, such as the series of steps taken to successfully complete a particular subtask.

    Agent learning from work and feedback to generate and leverage knowledge items,viewable from the Agent Manager.

    Agent learning from work and feedback to generate and leverage knowledge items,viewable from the Agent Manager.

    Try Antigravity today

    We believe Antigravity’s product form factor represents the next fundamental step function in agent-assisted development. Thus, our goal is to channel it into the best product offering possible for end users. Today’s public preview includes the following features:

    • Google Antigravity for individuals at no charge
    • Compatibility with macOS, Linux, and Windows
    • Access to Google’s Gemini 3, Anthropic’s Claude Sonnet 4.5 models, and OpenAI’s GPT-OSS within the agent, offering developers model optionality 1

    Learn more about the features of Antigravity in our docs and read more about how Antigravity can assist you by browsing various use cases. New features drop frequently, so keep up-to-date with this blog and socials at X, LinkedIn, and YouTube.

    Experience liftoff in 3… 2… 1…

    1. [1] We provide access to models to the degree we have capacity, with rate limits to prevent abuse and that are refreshed every five hours. Under the hood, the rate limits are correlated with the amount of work done by the agent, which can differ from prompt to prompt. Thus, you may get many more prompts if your tasks are more straightforward and the agent can complete the work quickly, and the opposite is also true. Our modeling suggests that a very small fraction of power users ever hit the per-five-hour rate limit, so our hope is that this is something that you won’t have to worry about, and you feel unrestrained in your usage of Antigravity. ↩